A direct-to-consumer Shopify brand
AI systems that run a Shopify brand.
A direct-to-consumer brand selling on Shopify, and four AI systems we built to run its operations: sales, marketing, production and fulfilment, and customer service. Each one stops rather than guessing. The merchant is anonymized here and no performance figures are quoted, because none were measured. What follows is what was built.
The store is the subject. Each automation is attached to it and built for it, and the page below takes them one at a time.
- solid
- Wired and running today.
- dashed
- Built or available, and deliberately not switched on.
That convention holds across every diagram on this page. The screenshots below are of the real systems, captured from running instances against their real data. Customer names, phone numbers, email addresses and postal addresses are redacted, and nothing else is: the chrome, the labels, the counts, the statuses, the dates and the records themselves are what the products actually show.
Sales automation
An outbound sales engine built around an agent that actually makes the calls. It phones leads, holds a real spoken conversation, qualifies them against a fixed questionnaire, and writes what it learned straight into the customer record as typed fields. The call is not a recording somebody listens to later. It is structured data the follow-up engine, the outreach experiments and the order rules all act on immediately.
The compliance layer is drawn as a bar the lifecycle has to cross, because that is what it is in the code: one module computes contactability and every outbound path calls it.
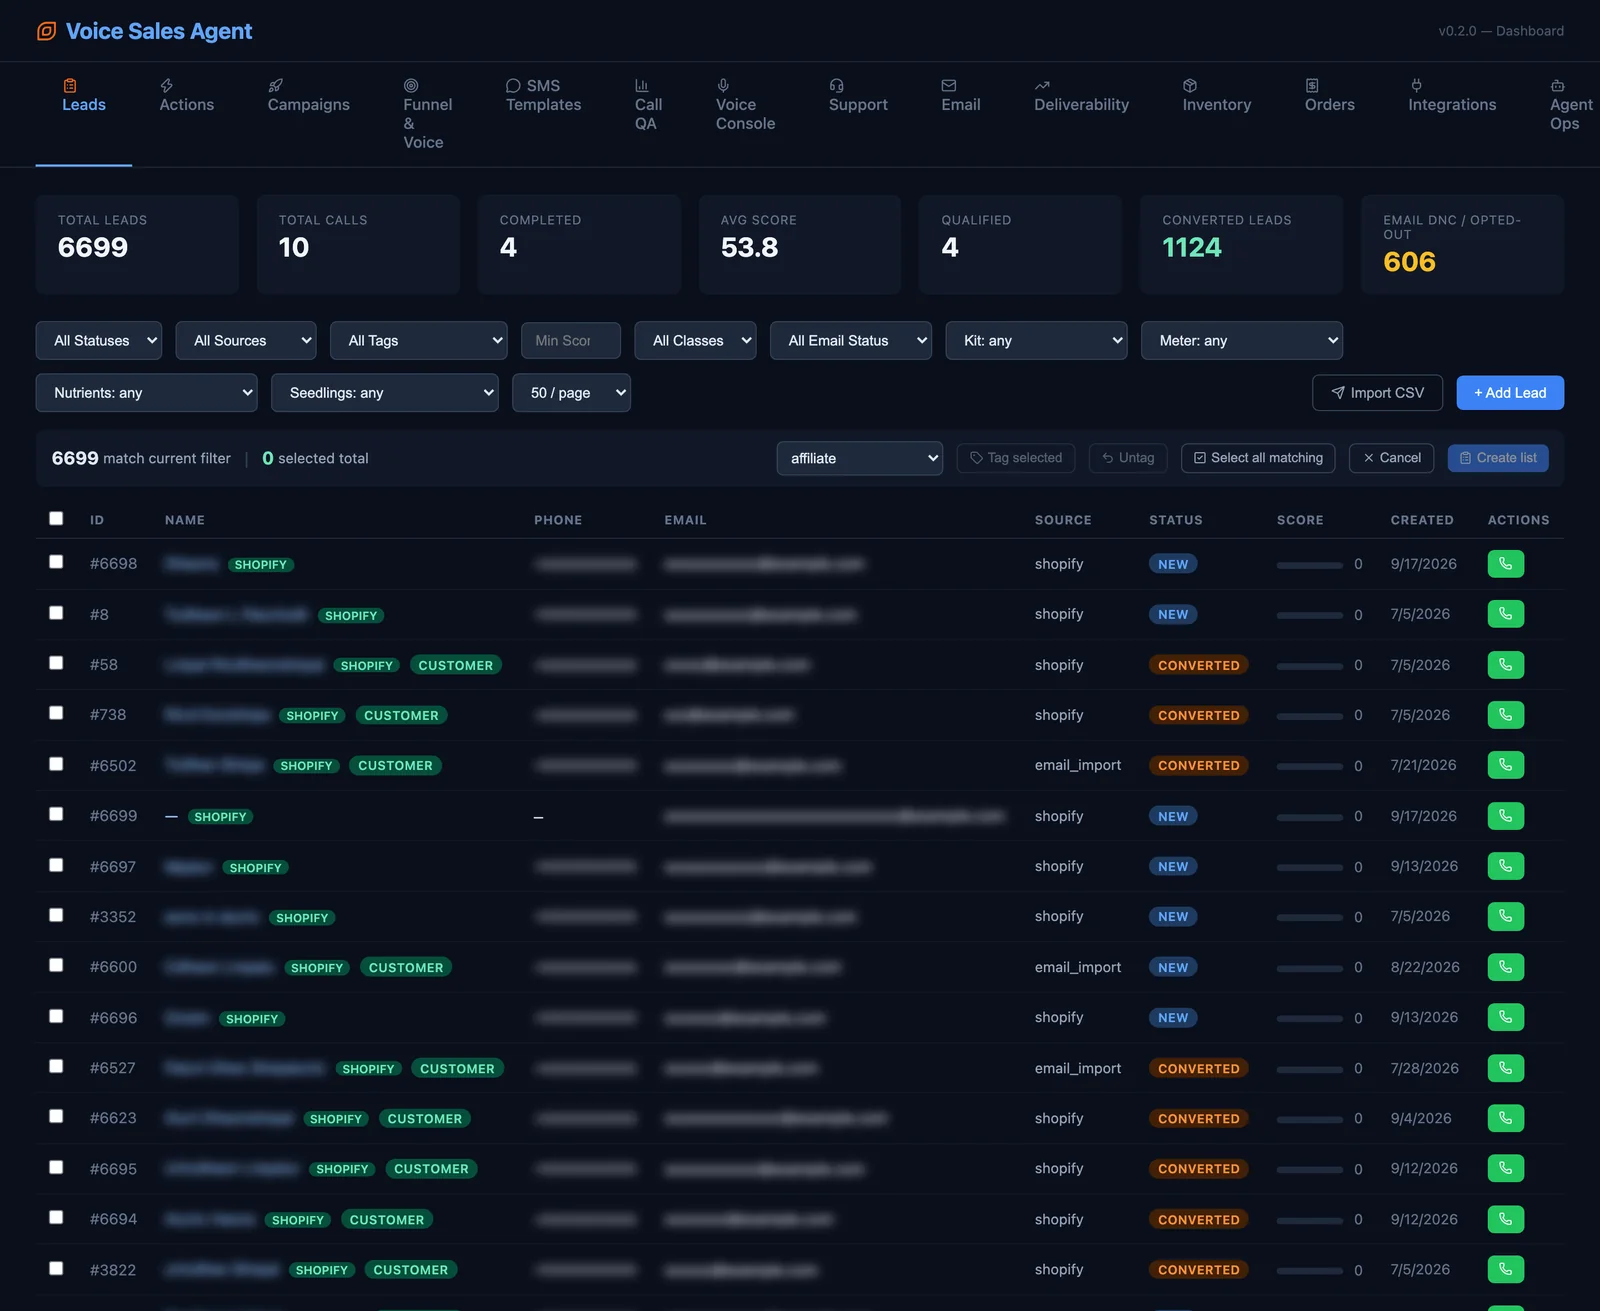
The whole pipeline in one view: where each lead came from, what the call scored it, and the contact state that decides whether it may be approached again. This is the merchant's real lead table. Names, phone numbers and email addresses are redacted; every source, status, score, tag and date on the screen is real.
- 01
The agent places the call and holds a real spoken conversation.
Speech in, agent, speech out, over a live telephony bridge with turn control managed explicitly. The platform's automatic turn detection is switched off and the microphone, the buffer and the commit points are handled directly, because a sales call has a different interruption tolerance than a generic assistant. Voicemail and long silences are first-class cases rather than edge cases.
- 02
Every call ends as a typed qualification contract, not a transcript.
A fixed, ordered questionnaire produces typed columns: fit assessment, growing experience, space type, motivation, budget band, timeline, pain points, product interests, objections with a category, preferred channel, contact consent and the best time to reach. The contract is enforced, so a field can never be declared, stored, and then silently never asked for.
- 03
Leads arrive from three directions and land in one contact record.
Ad-platform lead webhooks, bulk import and manual entry all resolve into a single unified contact, with tagging and lead lists on top. Duplicates are detected rather than assumed: a merge candidate goes to a review queue for a person instead of being collapsed automatically.
- 04
The follow-up engine fires every matching rule, not the first one.
The call outcome and its score band decide what happens next, and all matching rules run rather than the first match winning. Each action re-checks contactability and phone validity at the moment it fires, so a rule written weeks earlier cannot act on a contact who has since opted out.
- 05
Outreach is A/B tested with assignment that survives a restart.
Variant assignment is a pure hash over the experiment, a salt and the lead, so it reproduces exactly and is written only on first exposure, which keeps untouched leads out of the denominator. Results are reported as a confidence interval and a two-proportion test against control, and conversion is read from the order side rather than from a click.
- 06
One compliance layer that every outbound channel crosses.
A global do-not-contact flag blocks every channel outright; a per-channel opt-out blocks only its own. The rule is written once as a database predicate for audience queries and once in code for single sends, and both check global before channel, so the two cannot disagree. Texts additionally honour quiet hours and carry a guaranteed opt-out notice.
Script control belongs to whoever runs sales, not to whoever deploys code. Prompts for each call type are pulled from a hosted platform at call time with a short cache window, so a wording change takes effect on the next call with no release. The loader falls back through a local copy to a built-in default, which is what keeps that convenience from becoming a single point of failure.
A background scheduler runs the funnel on a tick, in four passes that are synchronous and testable offline: due nurture steps go out through the compliance layer, call-trigger rules create tasks for human reps, cross-sell gaps become draft campaigns, and inbound enquiries are swept. One invariant is stated in the code and holds across all four: the funnel never sends an email by itself.
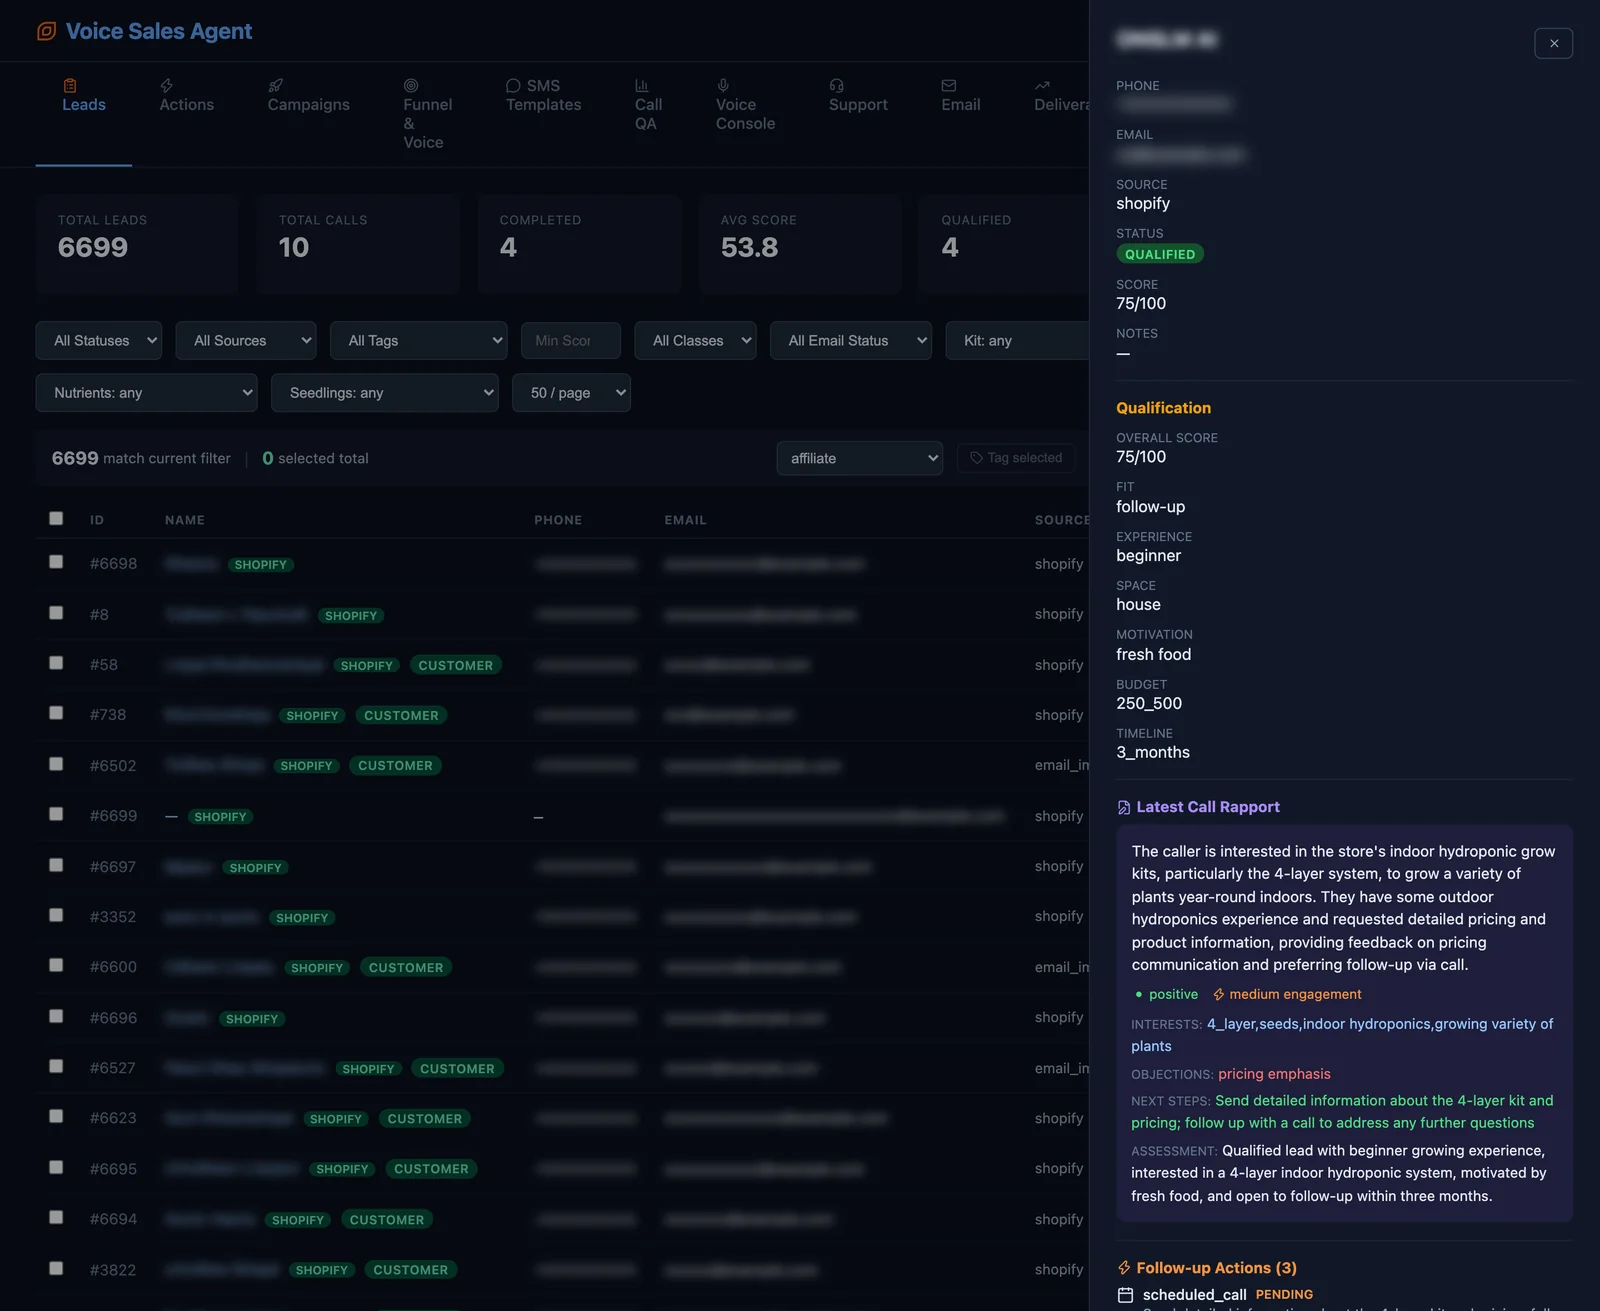
This is what one spoken conversation leaves behind. The call does not end at a transcript and a summary. It writes typed, validated fields that the follow-up engine and the email generator read, so a qualification becomes a routing decision rather than a note. The contact's name, phone and email are redacted, and so is any name inside the free text.
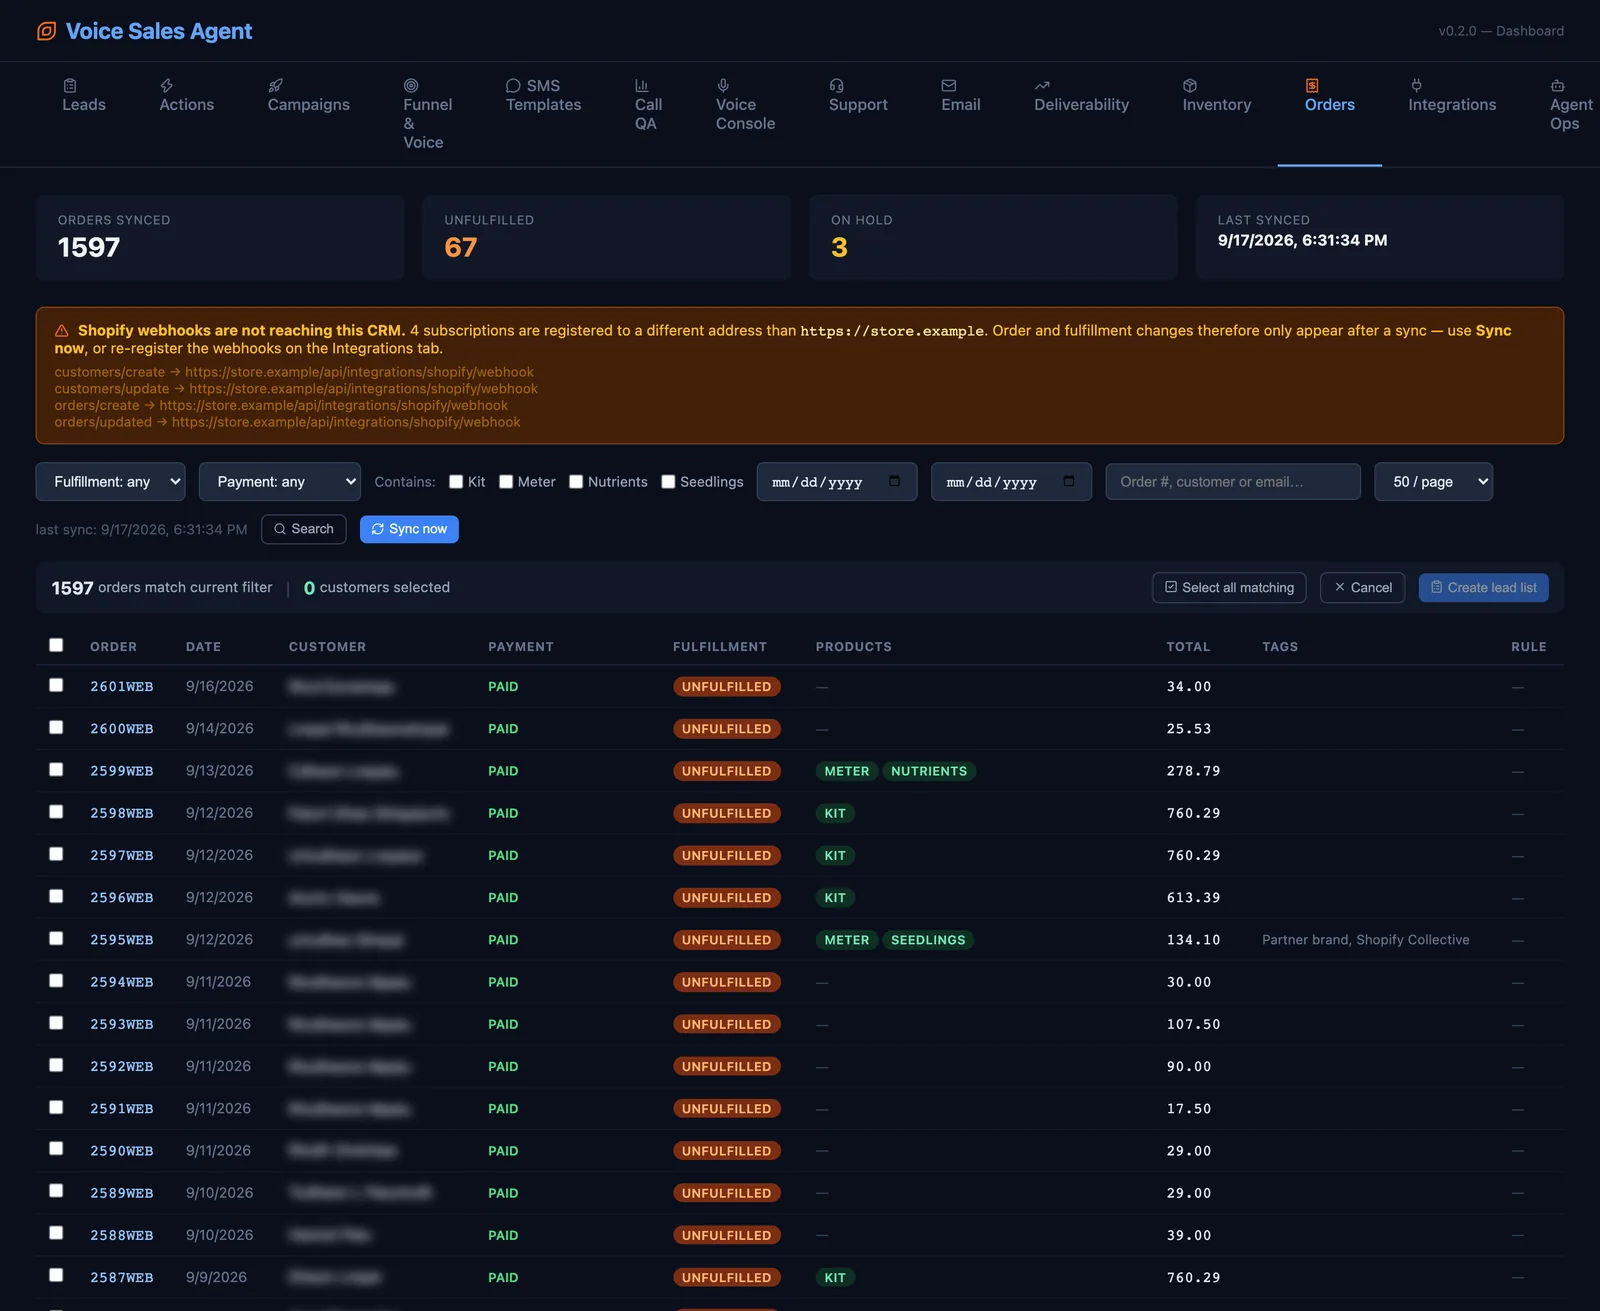
Store orders reconciled onto the contact record, which is what turns a lead list into a customer list. The banner at the top is the system reading its own wiring and reporting that the store's order webhooks are pointing somewhere else. It is real, current behaviour, kept in frame rather than edited out. Only the customer column is redacted.
Order rules are where an automation touches money, so they are built in two phases. A cheap database sweep proposes candidates; a live read re-confirms each one before anything is held or emailed. Every match is claimed in a ledger before the action runs, so a crash mid-action under-acts rather than acting twice, and a candidate that has already shipped is recorded as superseded rather than touched.
Cross-sell works the same way and stops one step earlier. Gaps in a customer's order history are read across the deduplicated profile and materialise as draft campaigns in a review-gated system. Nothing in that path sends, and nothing in it even generates copy without a person asking for it.
The honest commercial framing is speed and consistency at the top of the funnel. Every lead gets called, gets called promptly, gets asked the same qualifying questions and gets logged the same way, which is the part of outbound sales that degrades first when a human team is busy. The agent does not close deals unattended. It qualifies, routes, and hands a scored, structured lead to a person.
Scope as built: fifteen screens over roughly one hundred and eighty backend routes. A twenty-two column qualification record. Four funnel passes, three outreach channels, and one contactability rule expressed twice.
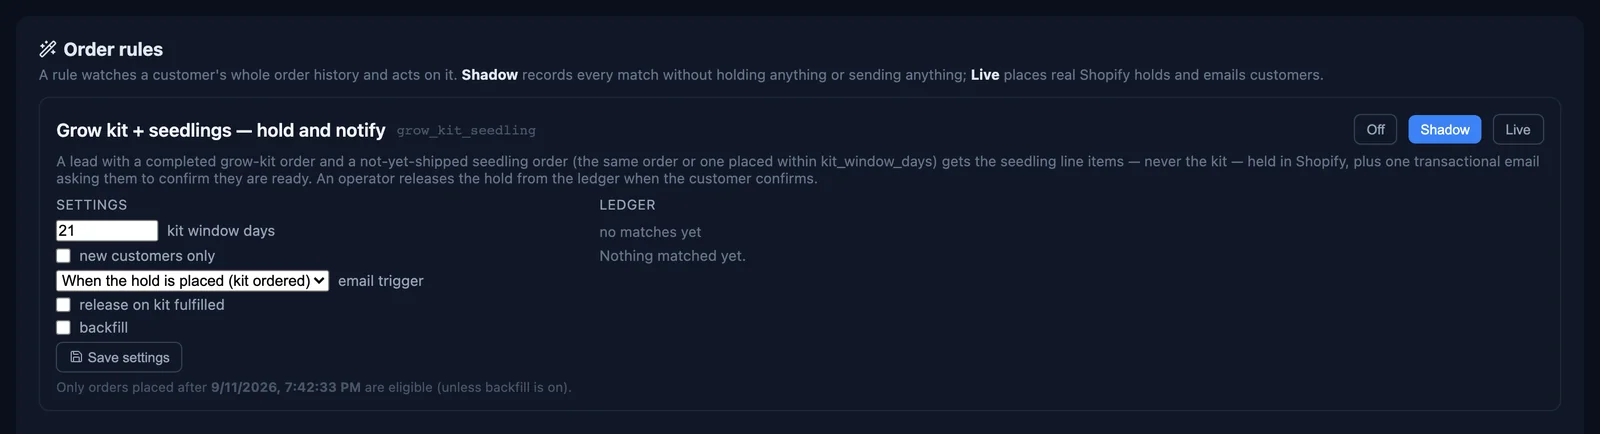
A rule that can hold an order or email a customer ships in shadow first. In shadow it records every match and sends nothing, so the behaviour can be read before it is trusted. The ledger reading empty is not a gap in the screenshot: it is what a shadow rule that has correctly held nothing looks like.
Marketing automation
A publishing engine that writes store content optimised for both search engines and AI answer engines, and refuses to publish anything it cannot cite. It pulls plant-care facts from the evidence base below, filters them for relevance to the article being written, validates that every claim resolves to a real and correctly attributed source, then creates the article in the store as an unpublished draft.
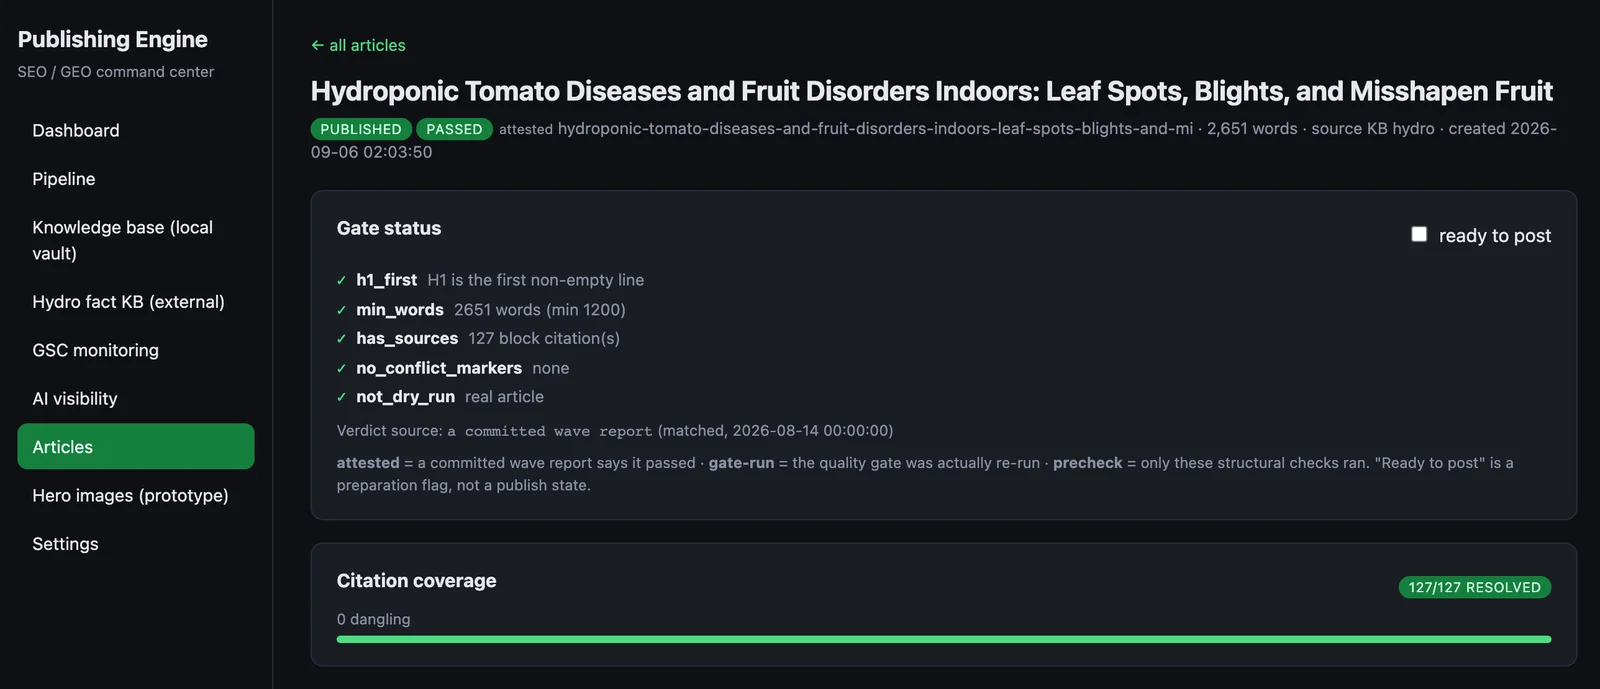
The gate is a precondition, not a review step. Structure, length, citation presence and the dry-run flag are checked separately because each fails differently, and coverage is reported as resolved against dangling rather than flattened into one score. Ready to post is a preparation flag, not a publish state.
- 01
Articles are written from retrieved, cited facts, never from model memory.
A single shared retrieval path resolves the article topic to crops and parameters, pulls the matching facts with their citations, and hands them to the writer. There is no second path a new feature could use to bypass it, and every claim has to resolve to an anchor in a real source.
- 02
A relevance gate removes facts that are true but wrong for this article.
Retrieved facts are judged against the article brief and discarded with a recorded reason when they do not apply. If too few survive, the run stops rather than drafting on thin evidence.
- 03
Every citation is verified against the live evidence base before publishing.
A referenced fact must exist, still be active, and actually belong to the source it was attributed to. A fabricated reference, a retired fact and a misattributed one all hard-fail the article. The structural gate runs alongside it, checking length and shape, and it runs before the project's own dependencies are installed so it cannot be skipped by a broken environment.
- 04
Uncited material is confined to one labelled section, and that boundary is enforced.
Content drawn from general knowledge lives under a single explicit heading. A near-miss heading is rejected so the exemption cannot be approximated into existence, and a citation appearing inside that section is treated as a fabrication.
- 05
It measures whether AI assistants mention the brand, not just where the page ranks.
Buyer-intent questions are put to a live assistant and scored for brand presence, competitor share of voice, and the list of questions where the brand is absent. Search-console monitoring sits beside it on a read-only scope, surfacing keywords with impressions but no clicks, and degrading to an empty state rather than an error when it is not authorised.
Store articles are created through the commerce platform's official API with search metadata attached, and default to an unpublished draft. Going live is a human action.
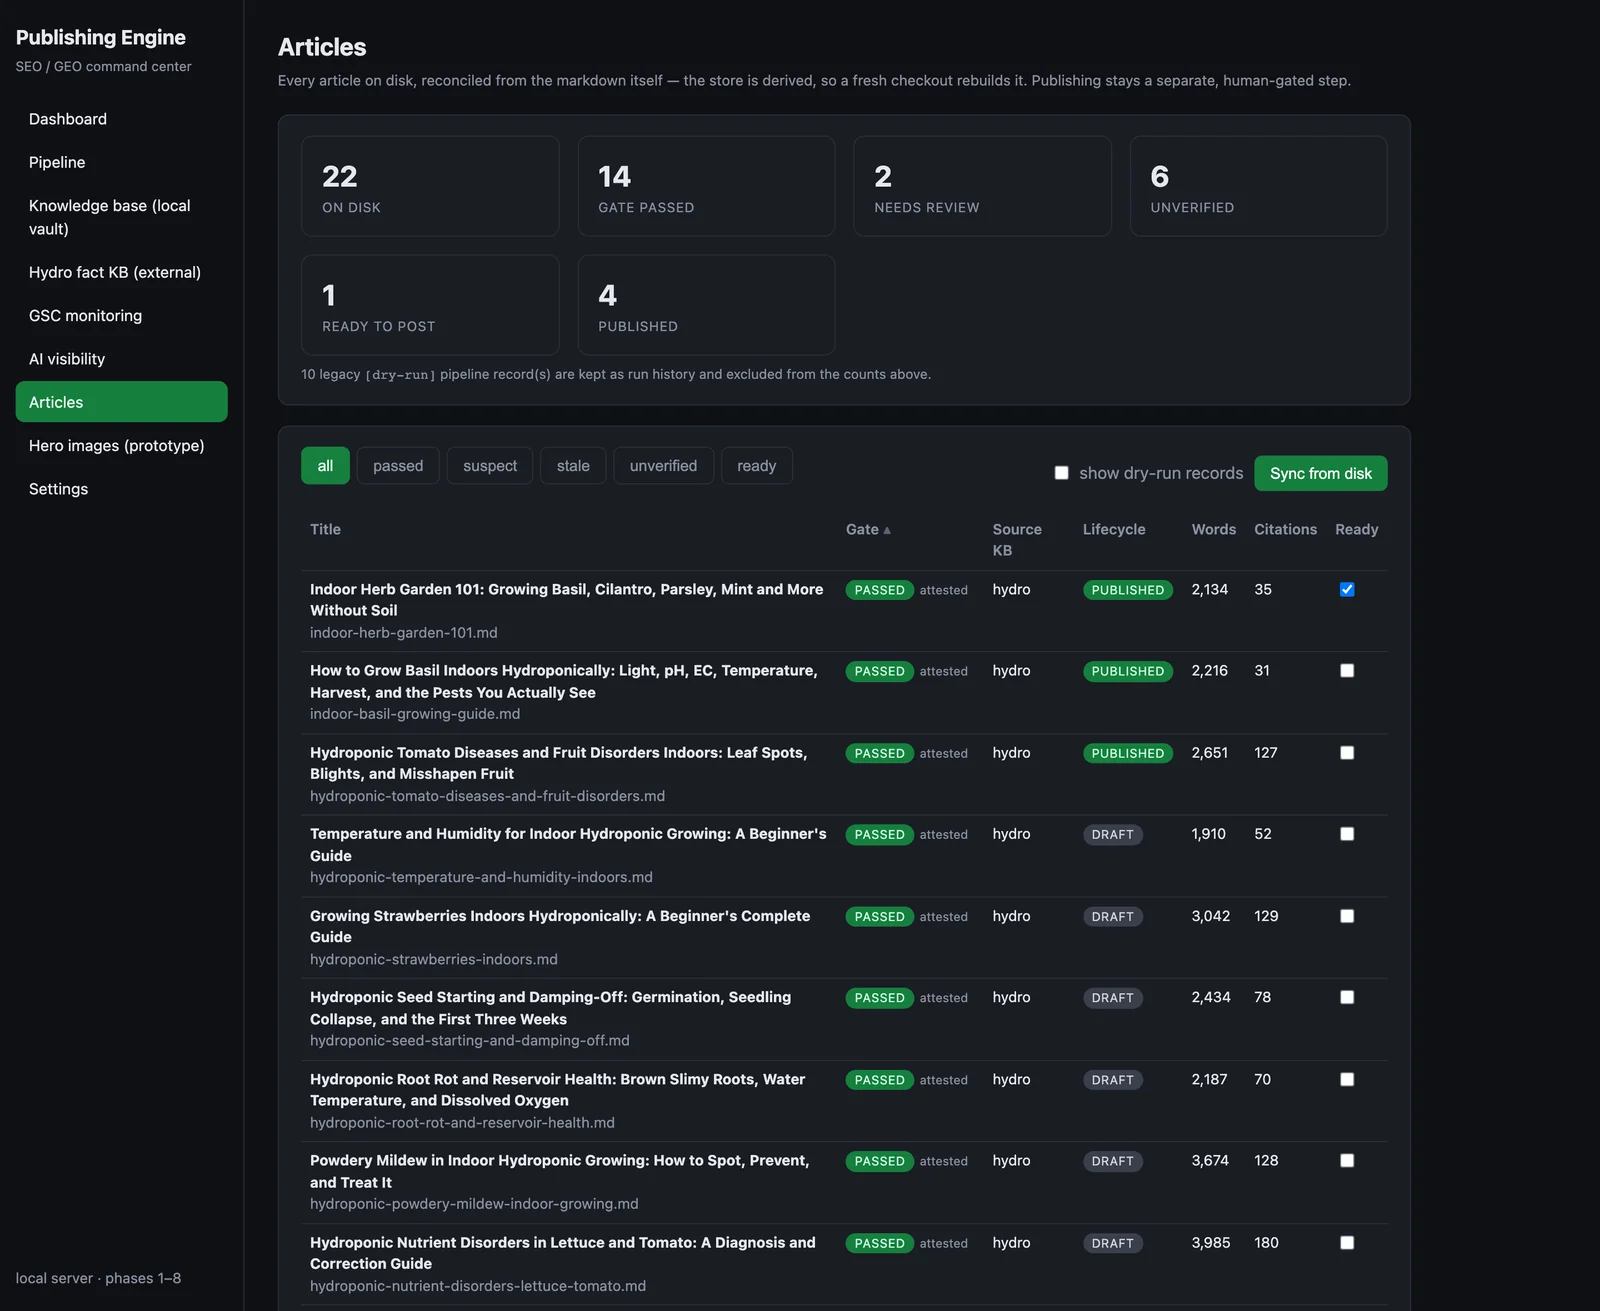
The list is reconciled from the markdown on disk, so a fresh checkout rebuilds it rather than trusting a cached view. Lifecycle state and gate verdict are separate columns on purpose: passing the gate is not the same as being published, and publishing stays a step a person takes.
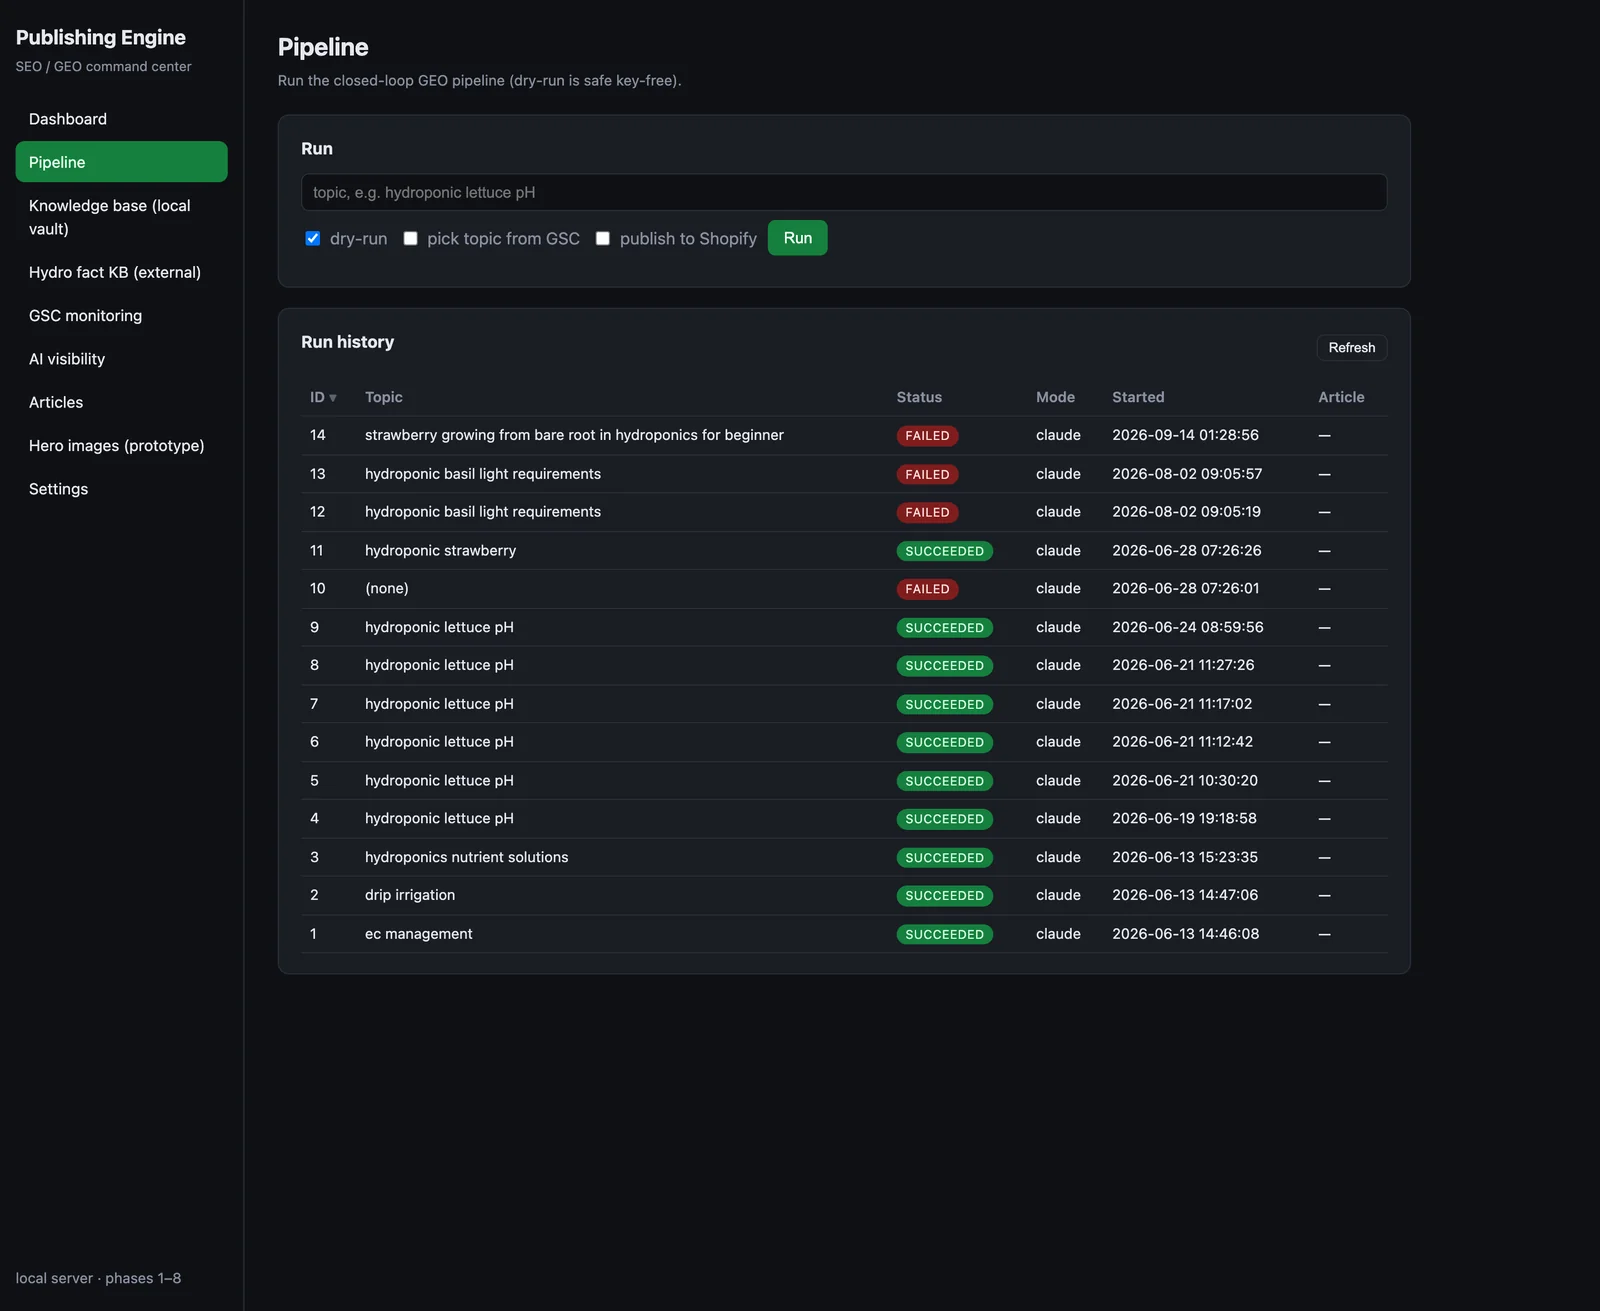
The loop runs dry by default, and publishing is an unchecked box rather than the path of least resistance. Failed attempts stay in the history instead of being cleared away, because which step refused and why is the part worth keeping.
Rank tracking answers a question customers are increasingly not asking. When someone asks an assistant what to buy, the page ranking third is not in the answer at all.
So the system measures both. Alongside rank and impressions, it puts buying questions to a live assistant and scores brand presence, competitor share of voice, and the questions where the brand never appears. That absence list is the content plan, derived from measurement rather than from a brainstorm.
The whole loop runs as one command and is built for unattended scheduling with a human approval point at the end. It takes a keyword opportunity, resolves it to crops and parameters, retrieves cited facts, filters them, drafts on the selected runtime, runs the gates, and files the result as a draft in the store. Any gate failure stops the run and records which step failed and why.
The commercial effect is content marketing without the usual liability. The bottleneck in AI-written content is not volume, it is trust. Making citation a publishing precondition rather than a review step turns production from a staffing problem into a scheduling problem.
What the marketing is written from
A cited hydroponics knowledge base
The articles above are only as good as what they are written from, so the source was built first. It reads the open scientific and horticultural literature on hydroponic growing and turns it into structured, machine-readable facts, each one carrying a citation back to the exact sentence it came from. Instead of a model that sounds confident, it produces numbers that can be traced. When it does not know something, it says so.
Two refusals sit on the path. A source whose terms are not cleared is never requested, and a fact whose quote cannot be found in the retrieved text is rejected and kept as a tuning signal.
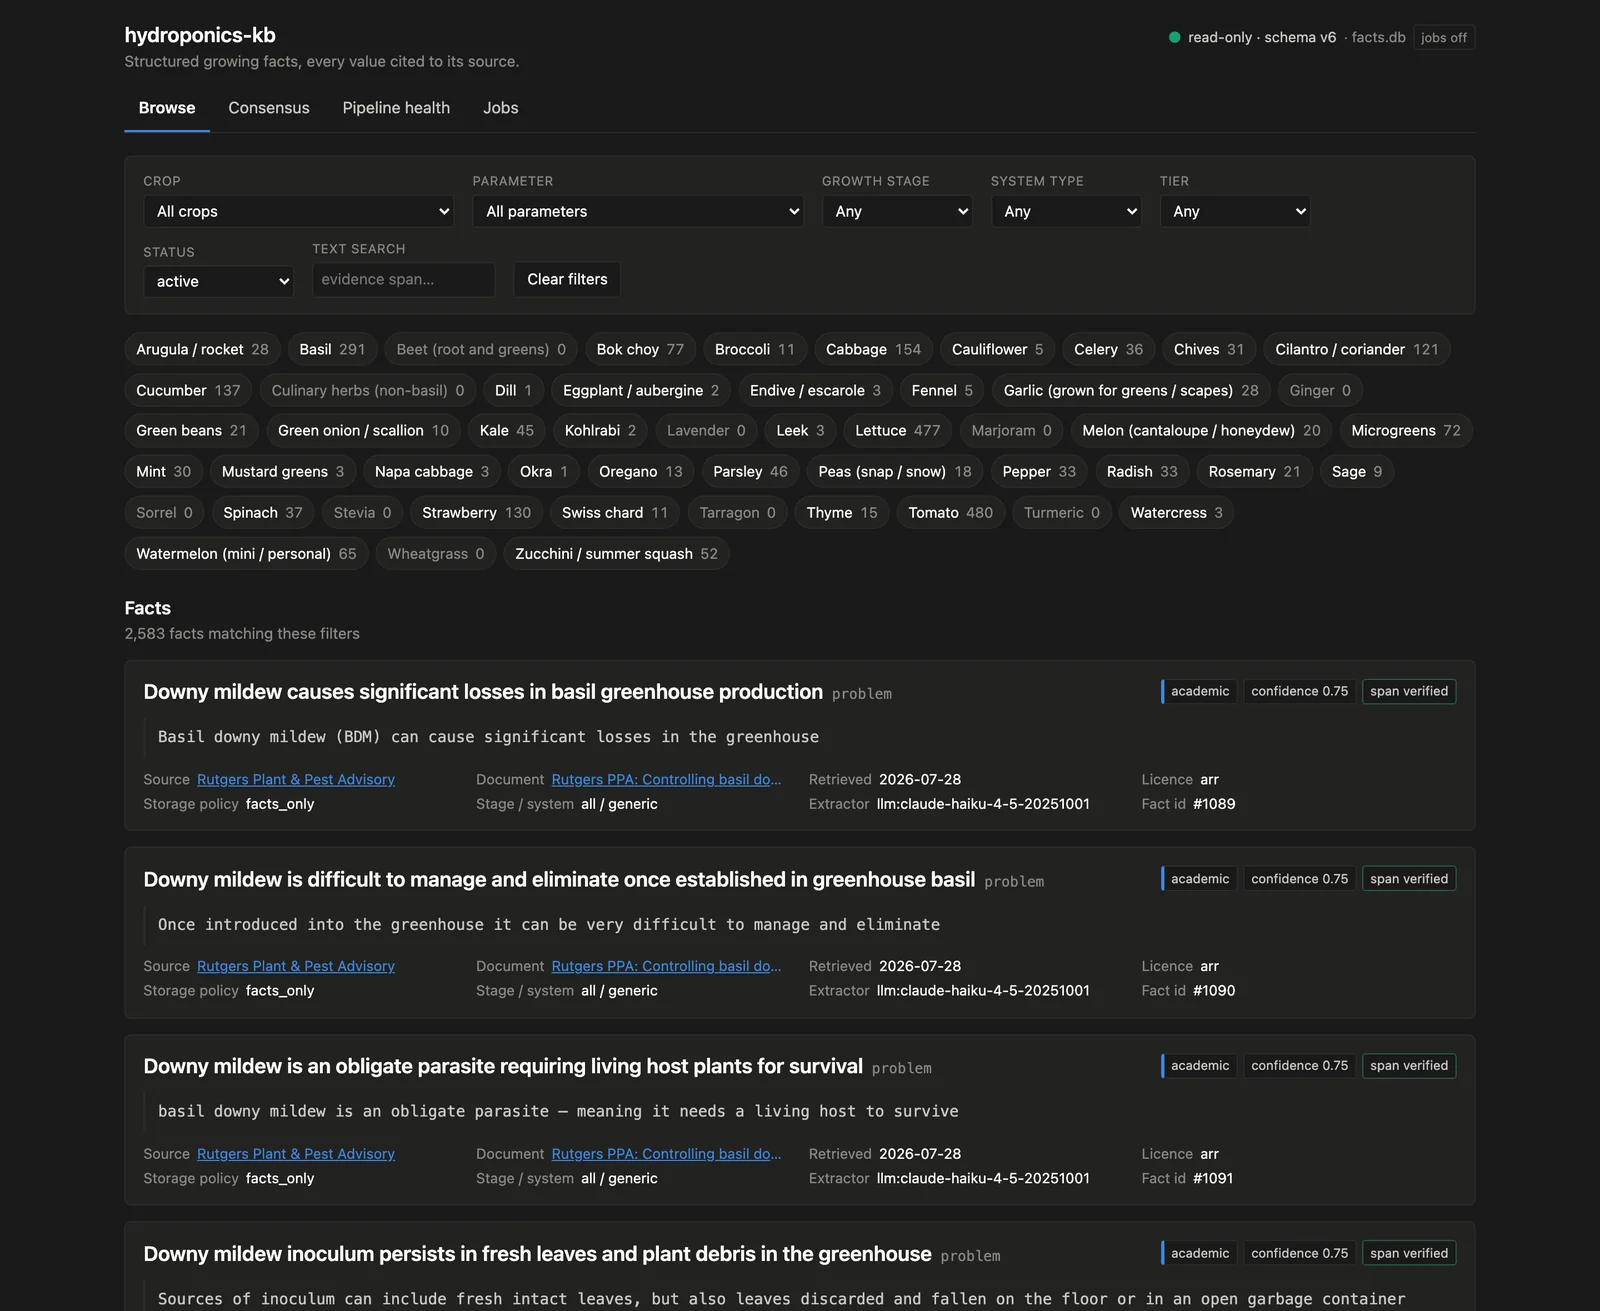
Every stored fact keeps the source it came from, the date that source was retrieved, the licence it was retrieved under, and the quoted sentence the value was read out of. Nothing reaches this screen that has not passed the span check first. No part of this frame is redacted, because it holds no customer data at all.
- 01
Every fact is anchored to the words that produced it.
Before a value is written to the database, the system checks that its quoted evidence is literally present in the stored source text. An exact match records the offsets; a match that differs only in whitespace is accepted at a confidence penalty; anything else is rejected and kept as a labelled failure. The pipeline asserts zero unverified spans as a standing invariant.
- 02
It refuses to crawl sources it is not permitted to use, and records the refusal.
Crawler permission and terms of use are two separate questions, and terms default to not cleared. A source whose terms have not been cleared issues no requests at all, rather than being fetched and then discarded. Excluded sources are registered as excluded rather than omitted, so the decision stays auditable.
- 03
Disagreement between sources is reported, not averaged away.
For each growing parameter the base publishes the median, the middle-half band, the observed range and a weighted mean, with an explicit disagreement flag when sources genuinely conflict. Below three facts or two distinct sources it returns nothing and names the reason, rather than calling thin evidence a consensus.
- 04
One knowledge base, four ways to read it, one query layer.
A command line, a web API, a browsing interface and a read-only connector for AI assistants all resolve through a single query layer. No query language lives outside it, and tests assert that each surface returns what the query layer returns, so no surface can drift from the others.
- 05
The gaps in its own knowledge become a work queue.
A read that names a subject the base has nothing for is logged and aggregated into a prioritised backlog, ordered by how many distinct topics touched it, then by miss count, then by recency. The suggested action names a step a person takes. There is deliberately no verb in it a scheduler could execute.
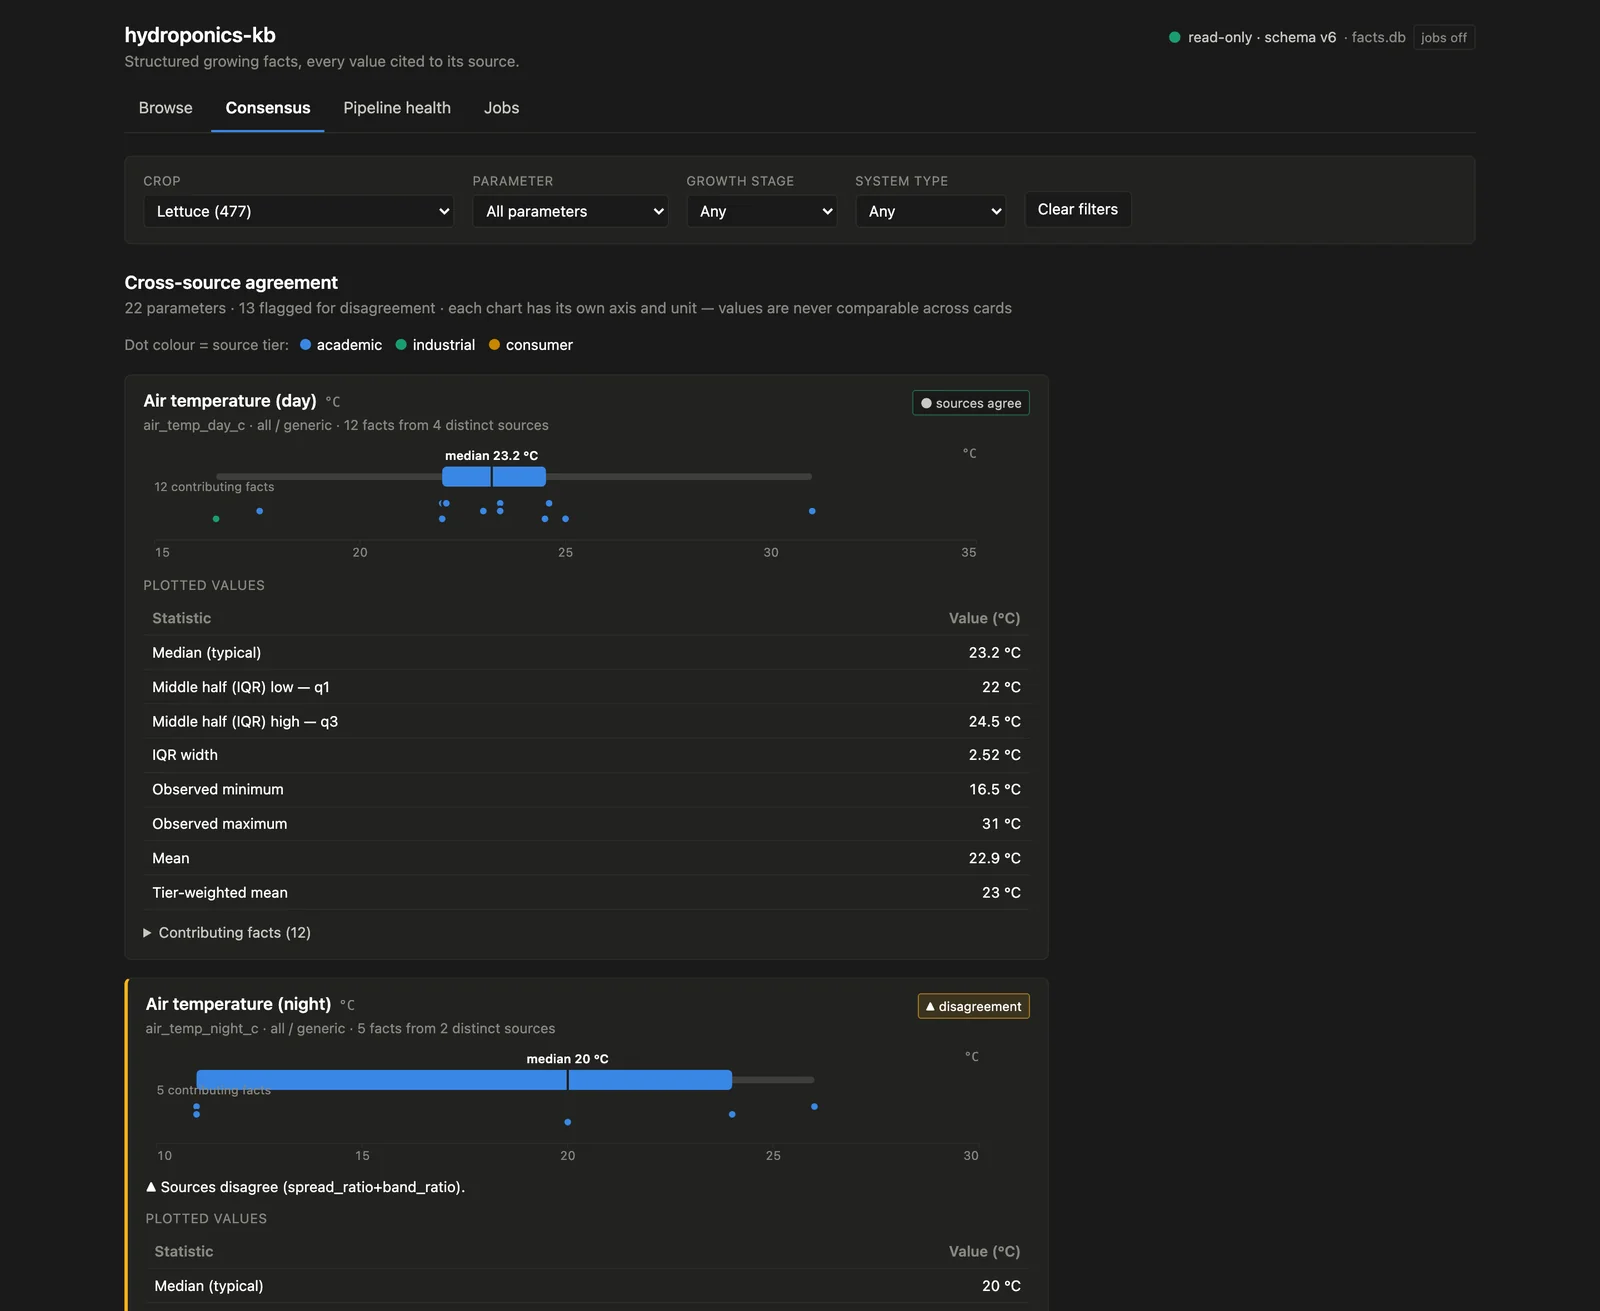
Where sources disagree the spread is drawn rather than averaged away. Each parameter carries its own axis and unit, and a parameter the sources genuinely conflict on is flagged as a disagreement instead of being resolved into one confident number.
Registry scope as built: 52 crops, 36 of them active. 26 growing parameters. 81 pest, disease and disorder entries. 35 registered sources, 5 of which are recorded as deliberately excluded. Depth varies by crop, which is exactly why the gap backlog exists.
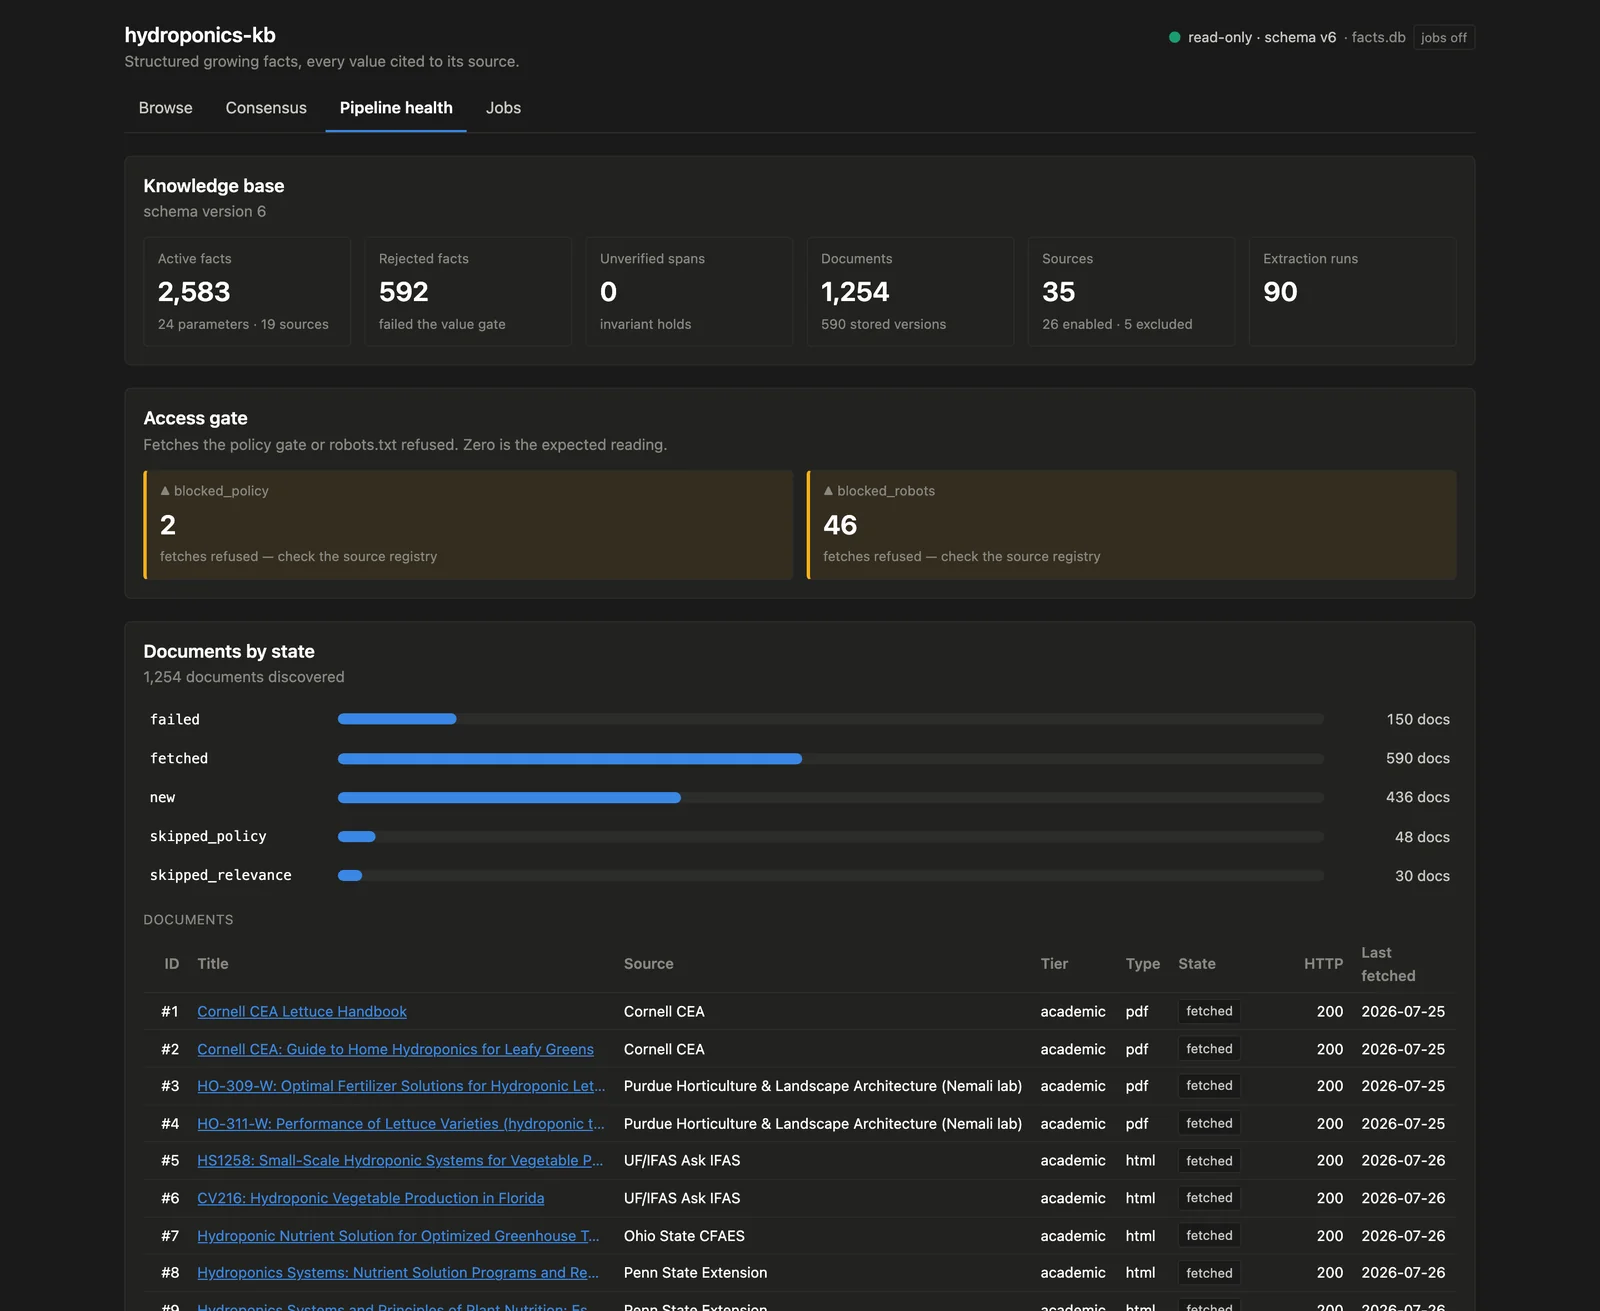
Refusals are readings here, not hidden failures. Values that failed the span check, fetches the source policy declined and documents skipped as irrelevant are each counted and kept, which is what makes the ingest path auditable from one end to the other. The unverified-span tile reading zero is the invariant, not a coincidence.
Ingest schedules itself. What is due lives in the database rather than in an external scheduler, and the re-crawl interval adapts: it doubles each time a document comes back unchanged and halves when it changes, so static references settle into a slow cadence while active pages stay warm. Improving the extractor triggers a targeted backfill rather than a full reprocess.
Read-only is enforced by the engine, not by convention. Read surfaces open the database in read-only mode, and the job routes are not even registered unless the process is started with the flag that enables them, so an unauthorised fetch is a missing route rather than a refused one. Adding a crop is a configuration entry with no code change and no migration.
Commercially, this is the asset that makes the content safe to publish. Every claim in a store article about pH, EC, temperature or spacing resolves to a fact that resolves to a sentence in a source, and the article fails if it does not. That is the difference between content a brand has to fact-check by hand and content it can carry.
Customer service automation
A support layer that learns the store's answers from the store's own history. It mines question and answer pairs out of resolved tickets, indexes them alongside the approved reply templates, and answers an incoming question only when the match is confident enough. When it is not, it returns nothing and puts the question in front of a person. Alongside it, identity resolution tries to tell which customer is writing, and says so plainly when it cannot.
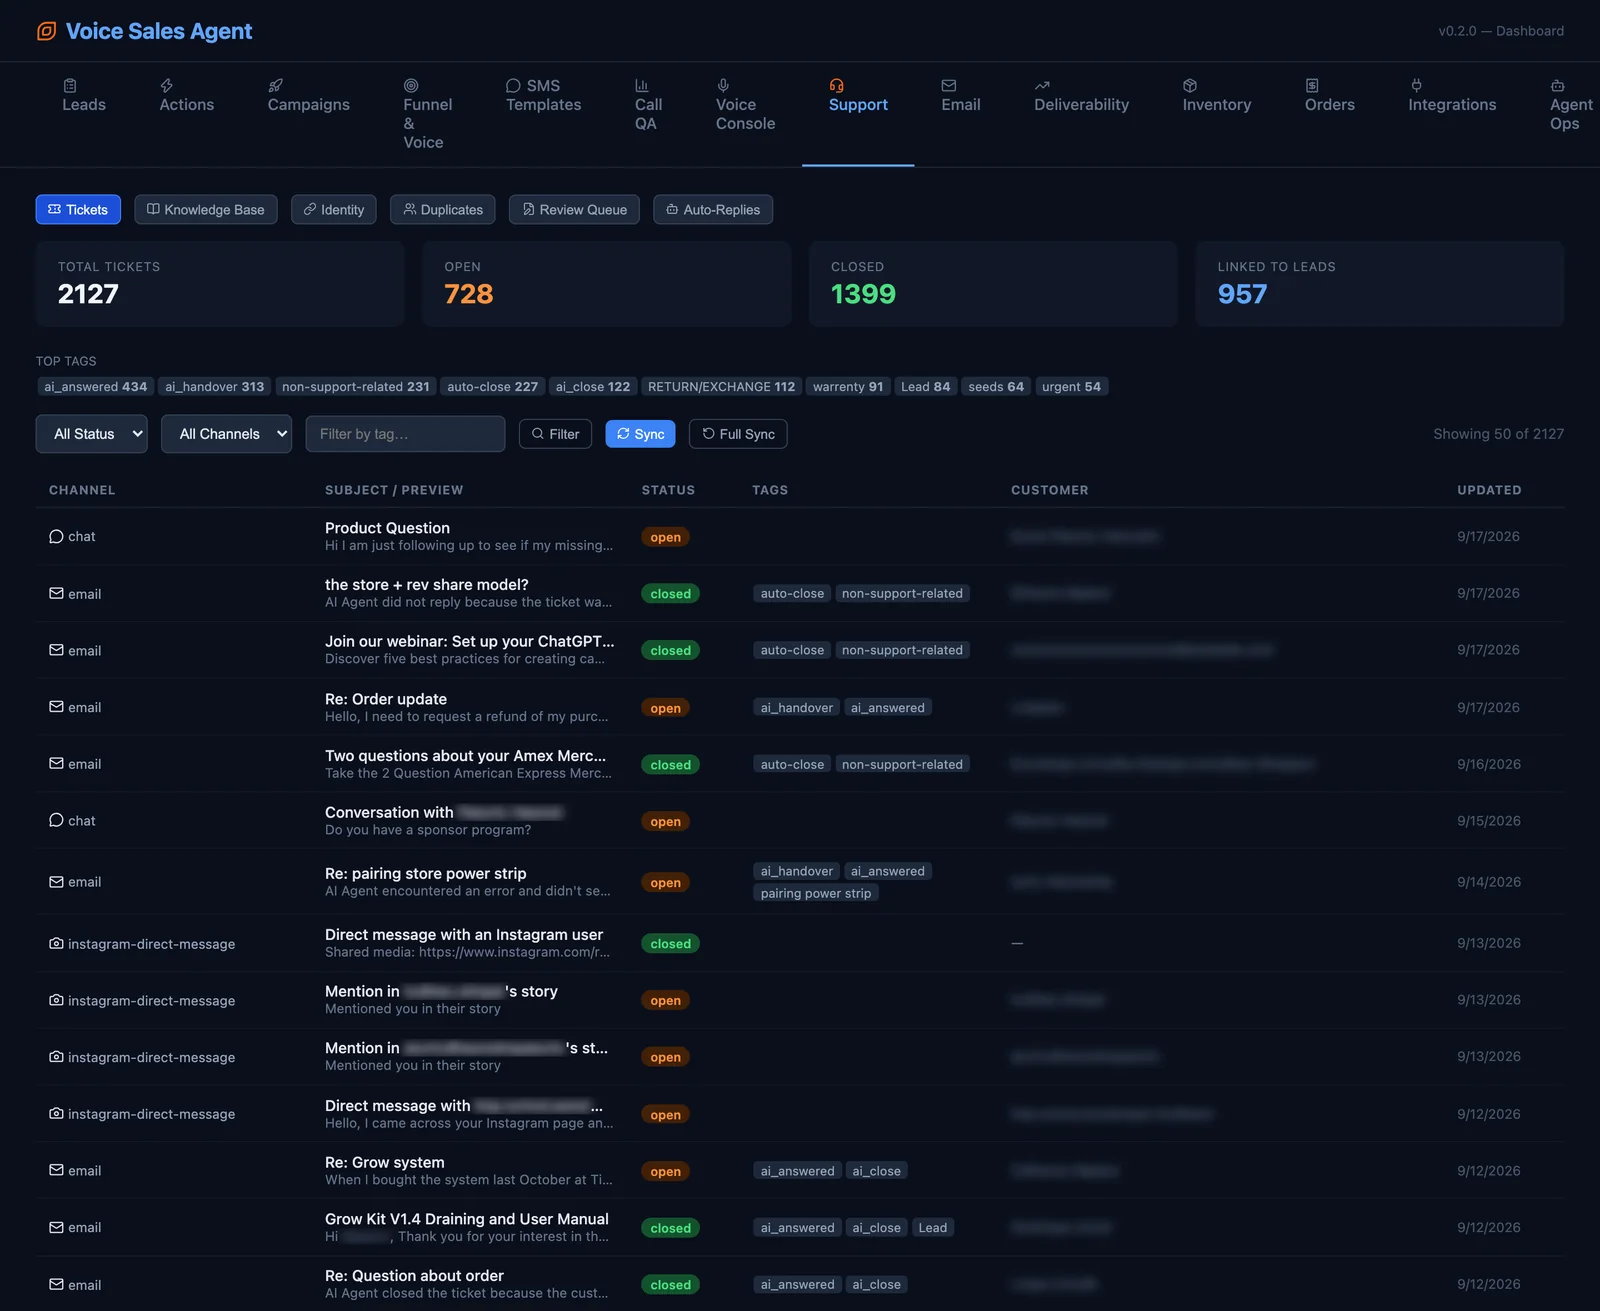
Every support conversation the store has had, synced from the helpdesk into the same database as the sales record, with the tag breakdown that decides which of them are worth mining. Customer names and any contact detail inside a subject or a preview are redacted. The channels, tags, statuses, counts and dates are real.
- 01
Answers are mined from the store's own resolved tickets.
A ticket becomes a candidate only when it is closed and carries at least one customer message and one agent message, with automation chatter excluded on both sides and quoted reply chains stripped. Re-extraction is idempotent through a ledger rather than a guess: one row per ticket ever considered, keyed on its message ids and its newest timestamp, so adding twenty tickets costs twenty extractions rather than starting over.
- 02
One index for every stage, exact rather than approximate.
Pre-sale, post-sale and general entries share a single embedding matrix and are separated by a filter applied after the comparison. The search is exhaustive rather than approximate, chosen deliberately: at this corpus size an exact comparison over an in-memory matrix is smaller, faster and correct, where an approximate index would be larger, slower and only nearly right.
- 03
It answers only above a confidence threshold, and returns no answer below it.
The lookup does exactly one of two things. At or above the threshold it returns the matched question and answer with its confidence and writes nothing. Below it, it returns no answer at all, records the question for a person, and pages nobody. Over-routing to the human queue is stated in the code as the correct direction to fail in.
- 04
Below-threshold questions become a queue a person works, not an alert.
Every question the index could not answer confidently lands in a review queue with the confidence it scored and the closest entries it found. Approving one writes a new entry back into the index, so the gaps the product actually meets are what the answer set grows from.
- 05
The auto-reply gate is rules-first, and the model never decides to send.
Rules own eligibility and the send decision; the model writes prose and reports only whether it can answer and how confident it is. Ten checks stand in front of a reply: self-send, automation senders, auto-submitted headers, per-thread and per-sender rate limits, unknown senders and do-not-contact among them. One reply per inbound message is enforced by a uniqueness constraint claimed before the send, so a crash mid-send under-replies rather than replying twice, and every decision including each refusal is written to a ledger.
- 06
Identity resolution auto-links on exact identifiers and refuses to guess.
An exact email match links outright and an exact phone match links just below it. A full-name match, an ambiguous match and a no-match are reported to a pending queue for a person and are never merged. The module does not merge contact records and does not invent one, so a support conversation is either attached to a known customer or visibly waiting for someone to decide.
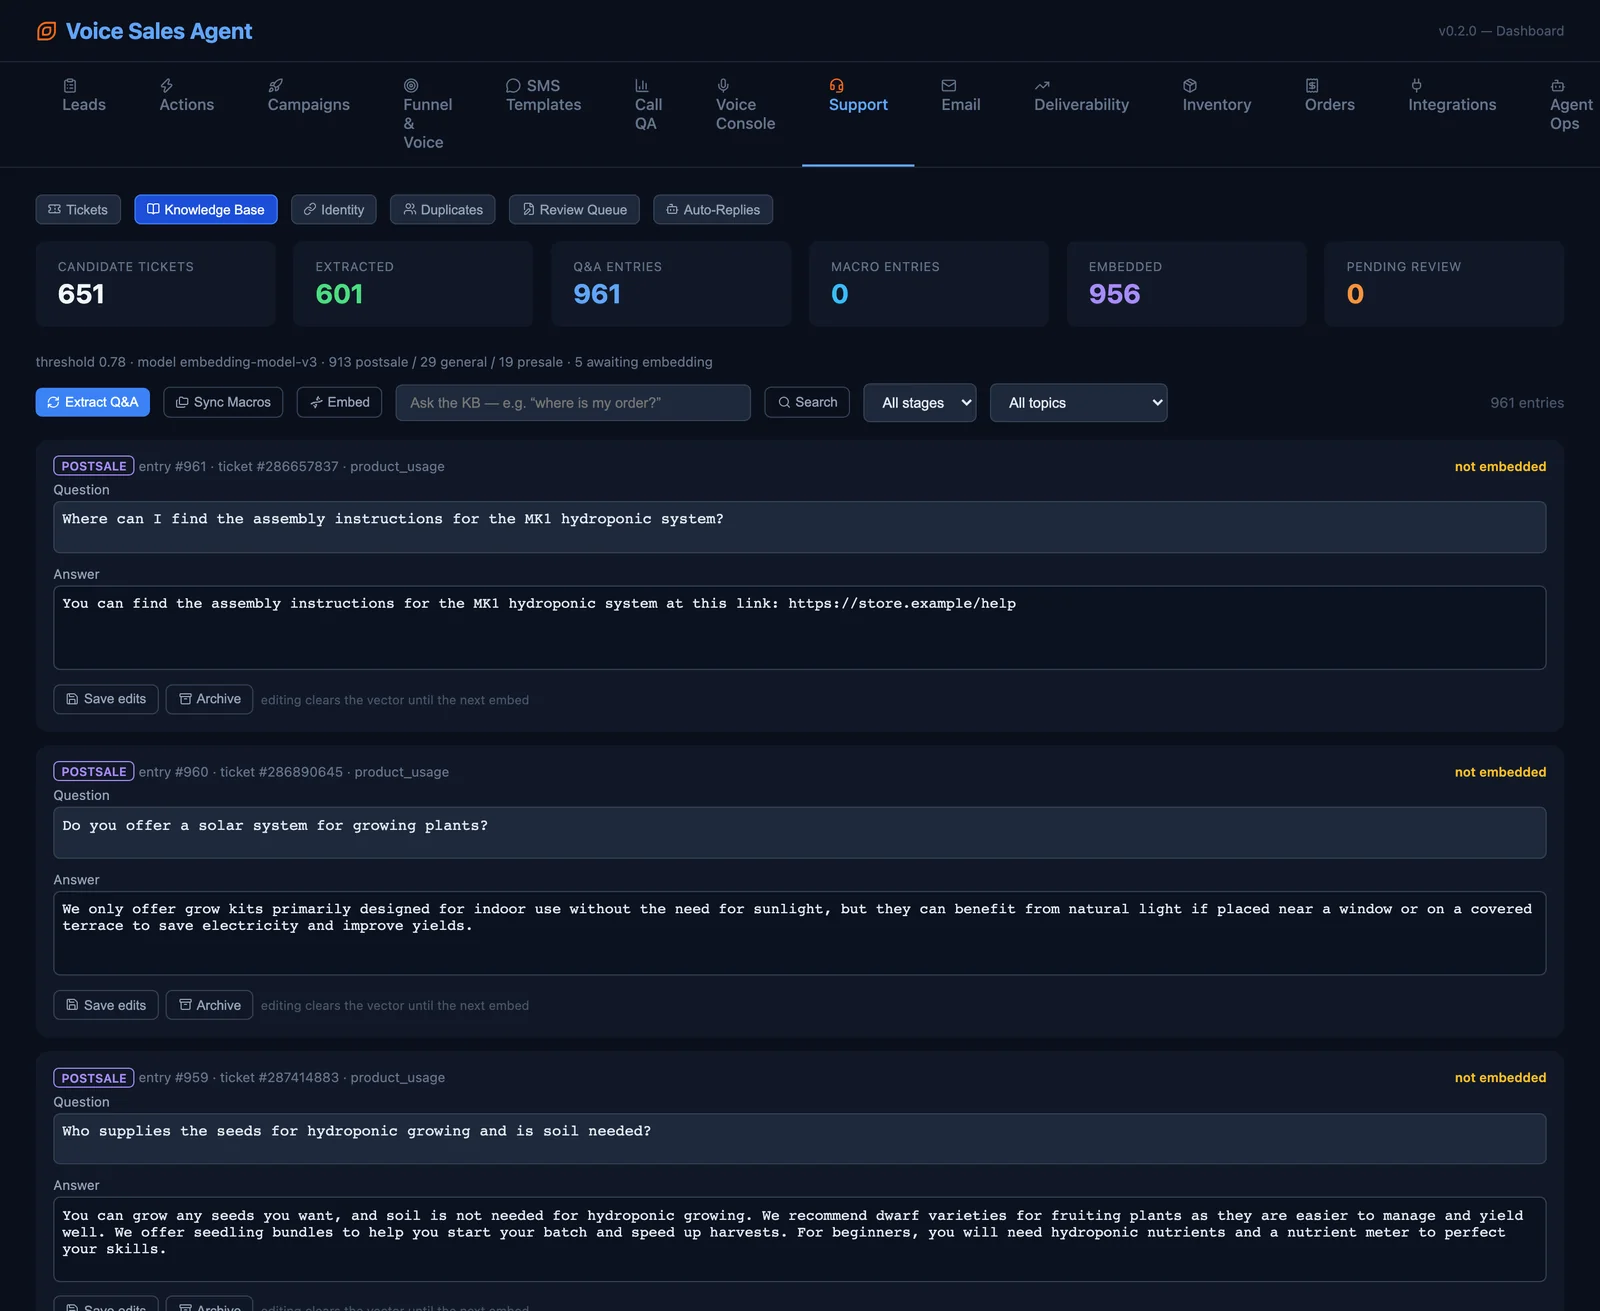
The index as the product reads it: how many resolved conversations were eligible, how many yielded a usable pair, how many are embedded and searchable, and the threshold an incoming question has to clear. Pending review reading zero means the queue has been worked, not that the gate is off. Only names and contact details inside a mined answer are redacted.
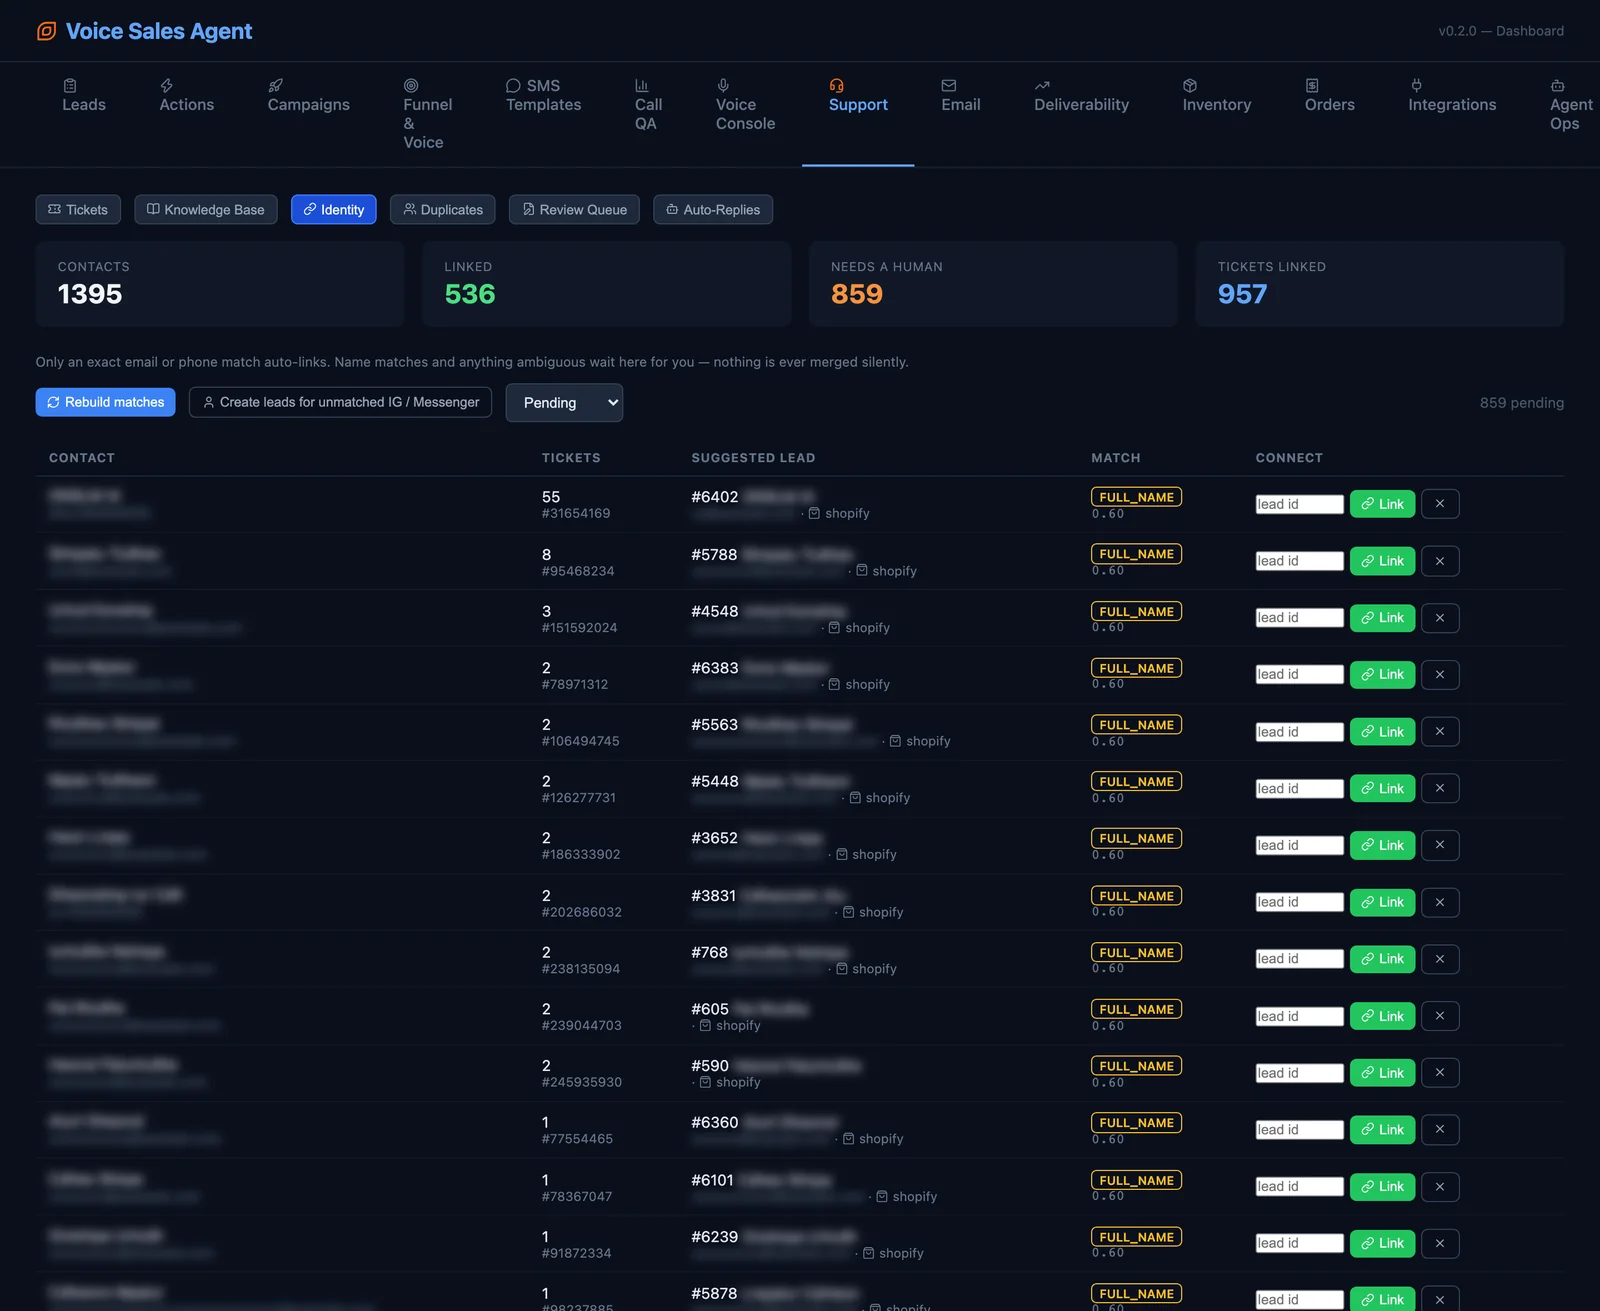
The two tiles are the whole argument. Exact identifiers link themselves; everything weaker waits for a person, and the count of what is waiting is on the screen rather than buried. Contact names and email addresses are the matched fields, so they are redacted. The tier, the confidence, the ticket counts and the status are not.
Scope as built: five support screens over one ticket store shared with the sales record. Tickets, mined answers, identity candidates, duplicates, the review queue and the auto-reply ledger. Three send modes, with off as the shipped default.
Tickets and their messages sync from the helpdesk on an incremental or a full pass, with a verify step that re-reads what it claimed to have imported. They can be filtered by status, channel and tag, and they carry statistics on which tags dominate and how many conversations resolve to a known customer, which is what makes the mining step selective rather than indiscriminate.
Approved reply templates are synced into the same index as the mined pairs, so a question can be answered by whichever is the better match rather than by whichever source was checked first. The index is invalidated on row count and on the newest update and embedding timestamps, so an answer edited by a person is live on the next question rather than after a rebuild somebody has to remember.
The commercial framing is deflection without denial. The volume that is genuinely repetitive, where is my order, how do I set the pH, what fits this kit, is answered from answers the store has already given and already stands behind. Everything else reaches a person faster, because it is not queued behind the repetitive part.
Work in progress
Production and fulfilment automation
An operations system that pulls the store and the overseas warehouses into one place, so stock, orders, fulfilment and warehouse cost can be read against each other instead of in three separate logins. It is deliberately built read-first, and it is the one tool here that is not finished.
Where it stands today
The reading and reconciliation layer is built. Every call that could change something in a live system is blocked by a safety gate that has to be opened explicitly, and both flags are off. Blocked attempts are logged rather than silently dropped.
The warehouse-facing reads are implemented but not currently connected. That is waiting on a production credential being issued, not on code. Syncing is manually triggered in the delivered phase, and fulfilment routing is an explicit exclusion from it.
Nothing in the lower lane has been switched on. The write path is built, previewable and tested, and it stays closed until someone opens it deliberately.
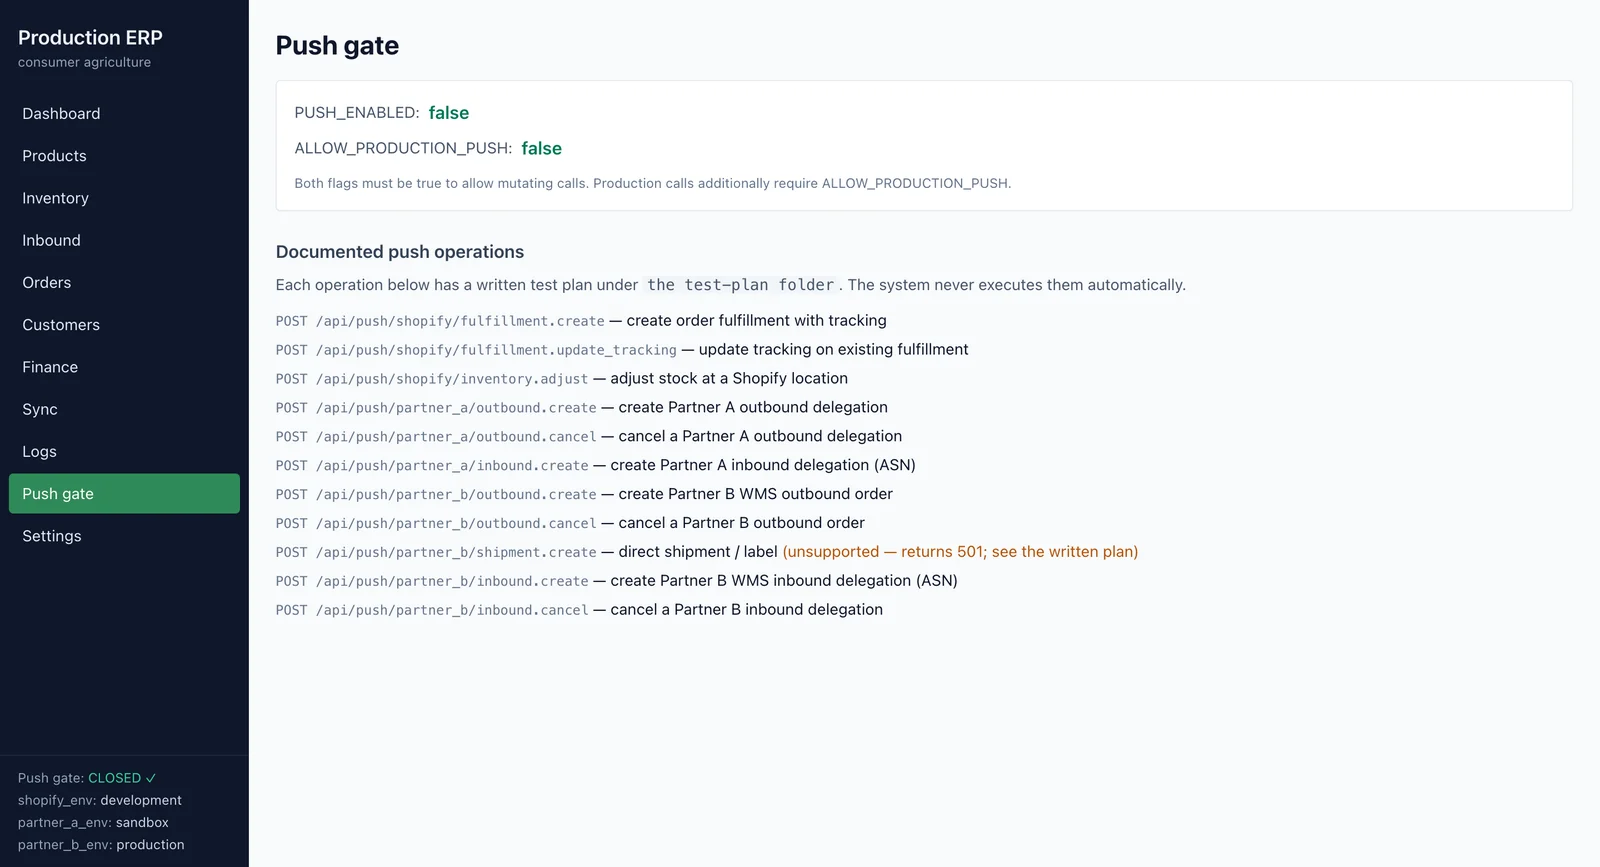
The diagram above states the rule; this is the rule as the product reads it. Every call that could change something outside the system is written down in one place, and the gate standing in front of all of them is shut. Both flags have to be set before any of it can run, and neither is.
- 01
A two-flag safety gate stands in front of every mutating call, and it is shut.
No write reaches a live system unless both flags are on, and both ship off. A blocked attempt records the provider, the operation, the direction and a summary of the payload, then throws, and the request surfaces as a distinct locked status rather than as a generic error.
- 02
What would have been sent is inspectable without sending it.
Every gated operation has a matching preview that returns the exact structured payload and the reason it is blocked, contacting no network at all. The system can show precisely what it would have done across the whole period before anyone trusted it to do it.
- 03
Store orders, products, inventory and fulfilments sync into one local ledger.
Paginated, cursor-based reads populate a single database, so the whole operation can be queried in one place instead of three separate logins. Each source keeps its own cursor, so a failed pass resumes rather than restarting.
- 04
Stock is tracked per batch across the warehouses.
Stock is held per batch, not only per product per warehouse, keyed on product, warehouse and batch number and carrying inbound date, expiry date and quantity. Warehouse SKU codes reconcile to local products, and a proposed mapping stays visibly distinct from a confirmed one.
- 05
Warehouse cost lines are read and reconciled against fulfilments.
Outbound billing lines are pulled and summarised so fulfilment cost can be read against revenue rather than estimated after the fact. Inventory, inventory detail, movement logs, inbound status and billing each sync as their own module.
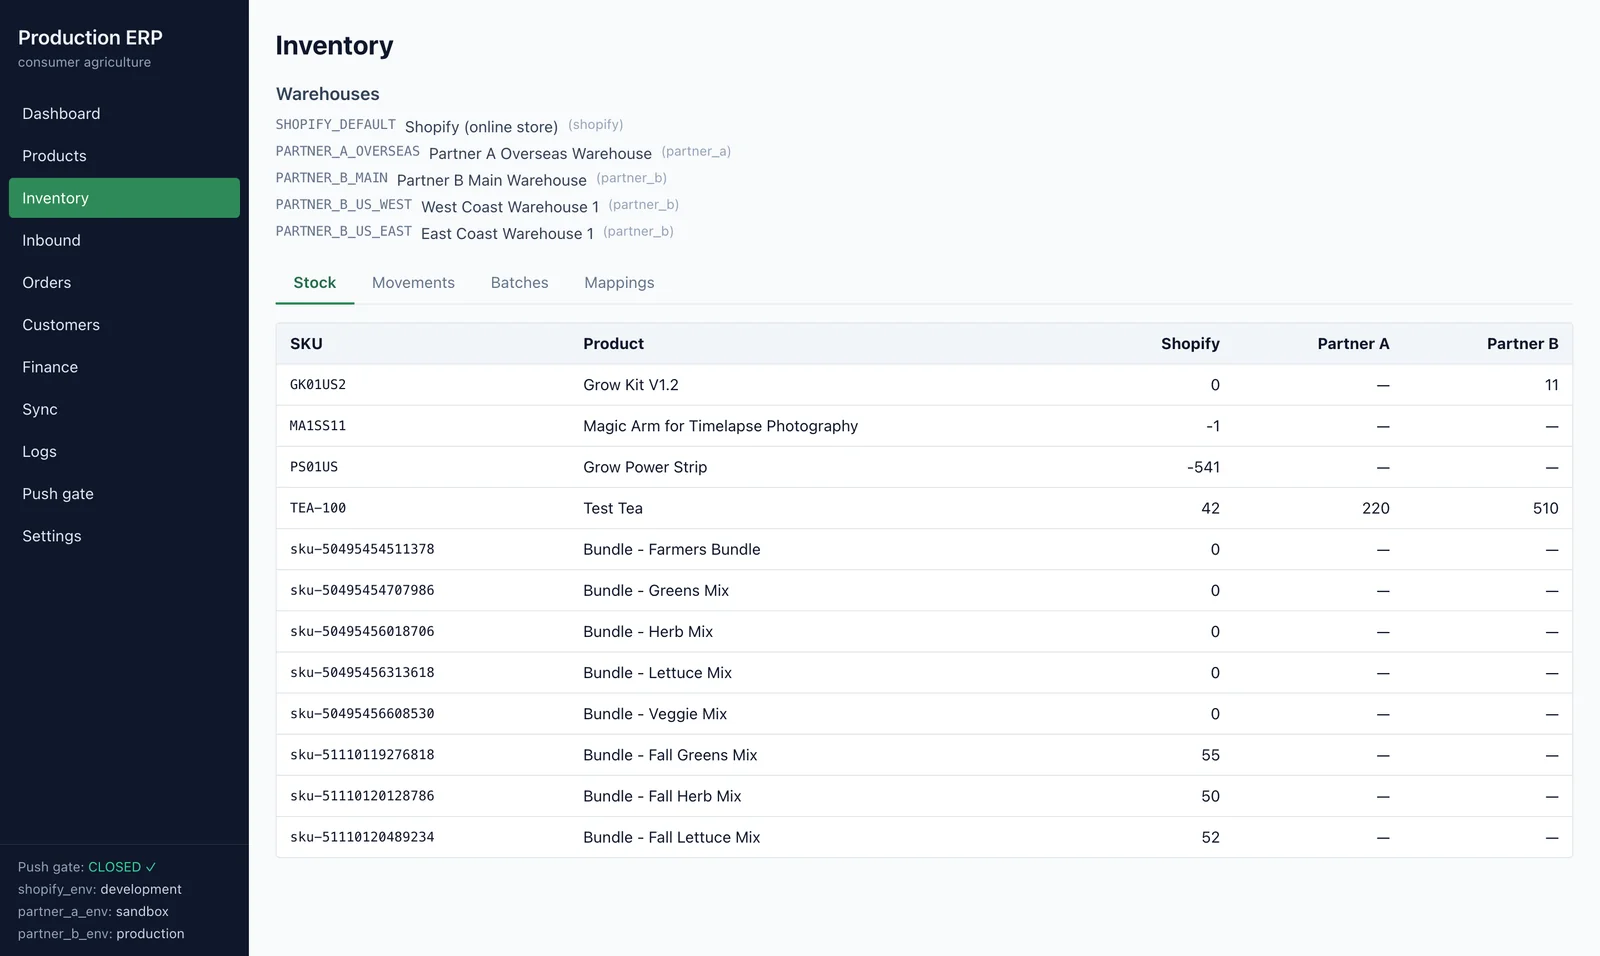
One stock picture across the store and the warehouses, read side by side instead of in separate logins. Where the counts disagree, including the impossible negative ones, the drift stays on the screen rather than being quietly reconciled away. Finding it is the point.
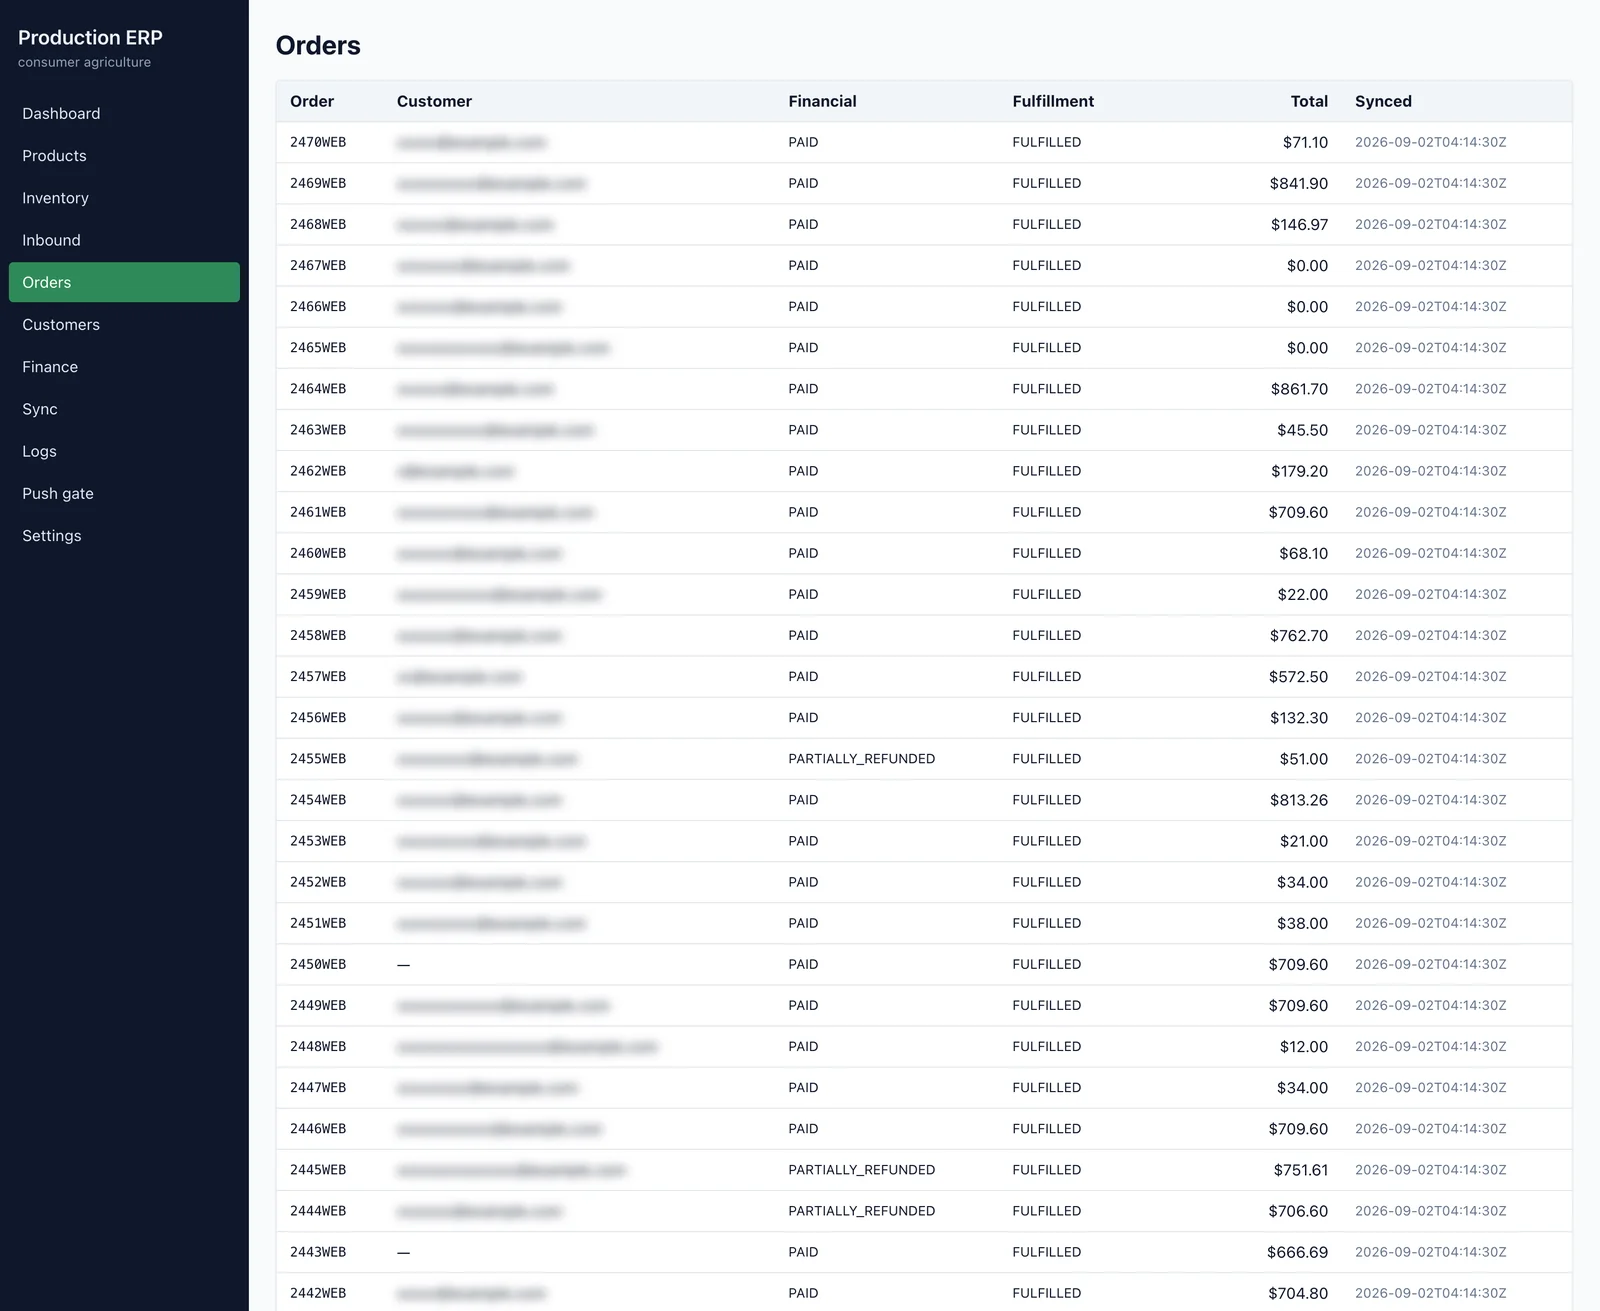
The store's orders as the operations ledger holds them, which is what fulfilment state and cost are later read against. One column is the customer, and that column is redacted. Order numbers, statuses, totals and sync times are real.
Eleven operational screens over thirteen backend route modules: dashboard, orders, products, inventory, inbound, customers, finance, sync, push, logs and settings.
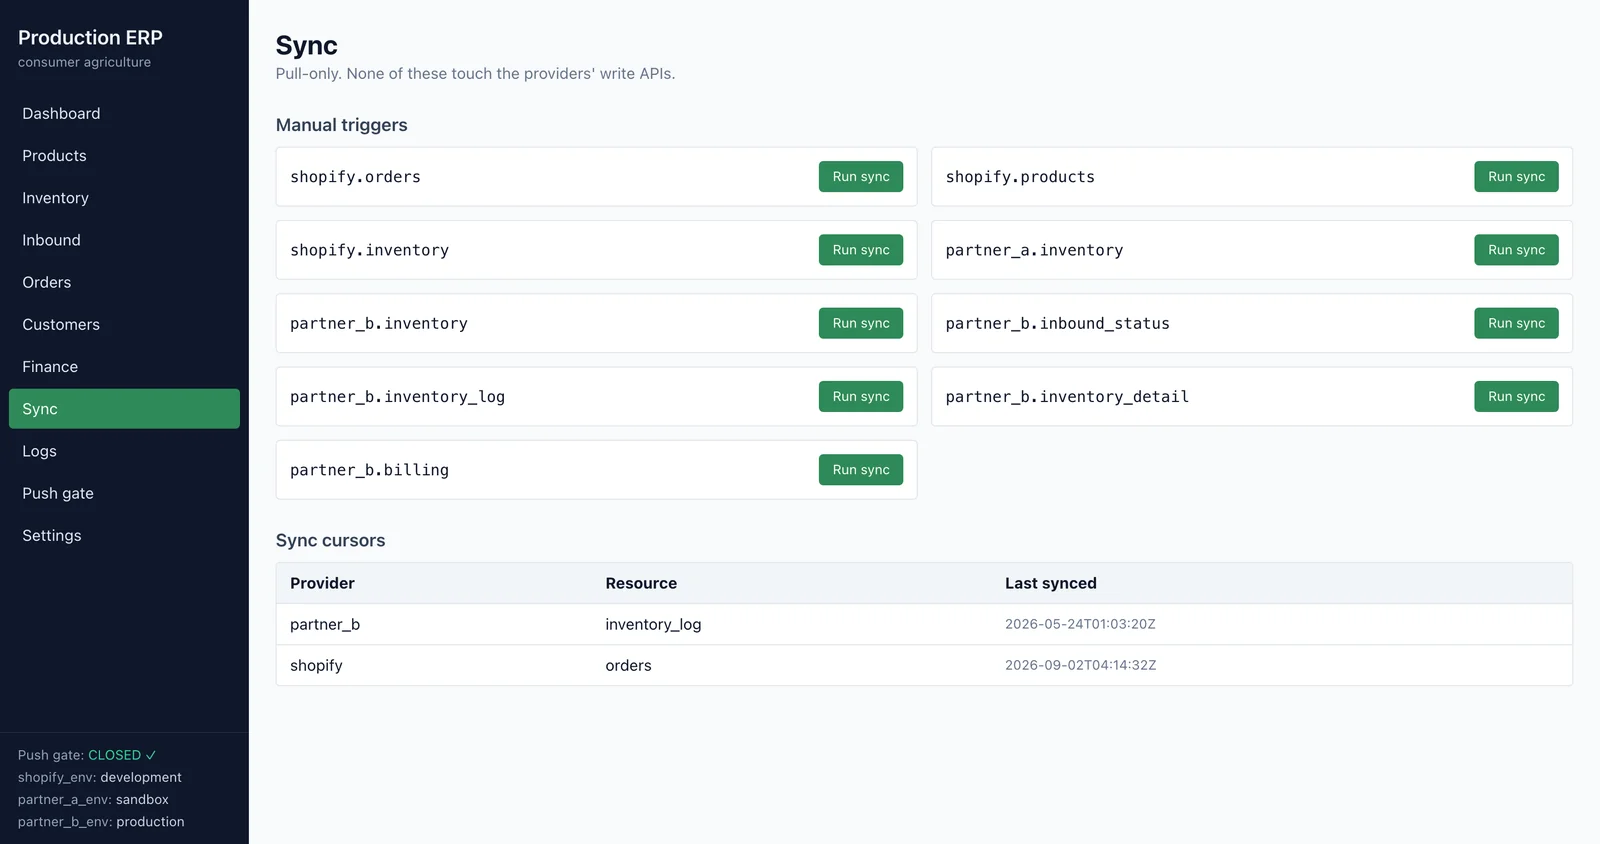
Ingestion is pull-only and manual in the delivered phase. Nine triggers, not one of which touches a provider's write API, each with a cursor recording where the last read stopped. Nothing on this screen can send anything to anyone.
Tracking batch number, inbound date and expiry alongside quantity is a schema decision made before the write path exists, which is what makes expiry-aware and age-aware stock reporting possible later without migrating historical data.
The commercial relevance here is margin visibility and exception handling, not automation volume. Reconciling store revenue against warehouse fulfilment cost per order is what turns a product catalogue into a margin picture, and an exception feed is the difference between finding a stuck shipment when the customer complains and finding it the same day.
This is the layer that keeps the customer-facing tools honest about what can actually ship.
Where an agent belongs, and where it does not
This is the written position in the repository for a later phase. None of it is running today, and it is here because the boundary is the interesting part.
Earns its keep, read-only, proposes for a person to act on
- Exception triage: inbound lines with discrepancies, outbound orders stuck past their expected window, shipments with tracking but no scan, cost lines that reconcile to no fulfilment.
- SKU-mapping proposals, surfaced for one-click human approval.
- Drafting warehouse dispute tickets for a person to send.
- Proposing a fee-category table from real invoices rather than guessing at the split.
Must not go
- Anything behind the safety gate. Order creation, cancellation and inbound delegation move physical goods in a warehouse.
- Browser-driving a third-party warehouse console, which means storing warehouse credentials against an interface that can change silently.
- Deciding which system owns a sales channel. That is a policy written down once, not adjudicated per order.
Want a system that behaves like this?
The four automations above were built for one store selling hydroponic growing equipment. The patterns behind them, gated writes, cited claims, and human approval where confidence is low, transfer to most operations that need to be right rather than merely fast.